Showing page 3 of 64
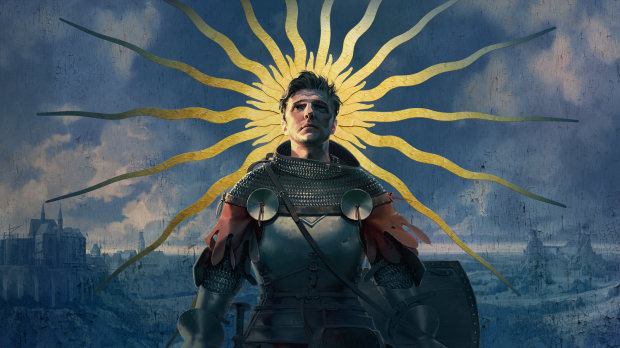
Kingdom Come: Deliverance 2’s director tested leaked DLSS 5 and found it fixes shadow rendering and facial detail the engine couldn’t handle. Here’s why the AI-slop narrative misses the point.
The Engram approach using N-gram embedding tables is reshaping how small models reason by offloading memorization to O(1) lookups. Here’s why the hype misses the real breakthrough.
FreeToken orchestrates CPU, GPU, VRAM, and RAM to run 753B MoE models on a single workstation card. Here’s how the memory dance actually works.
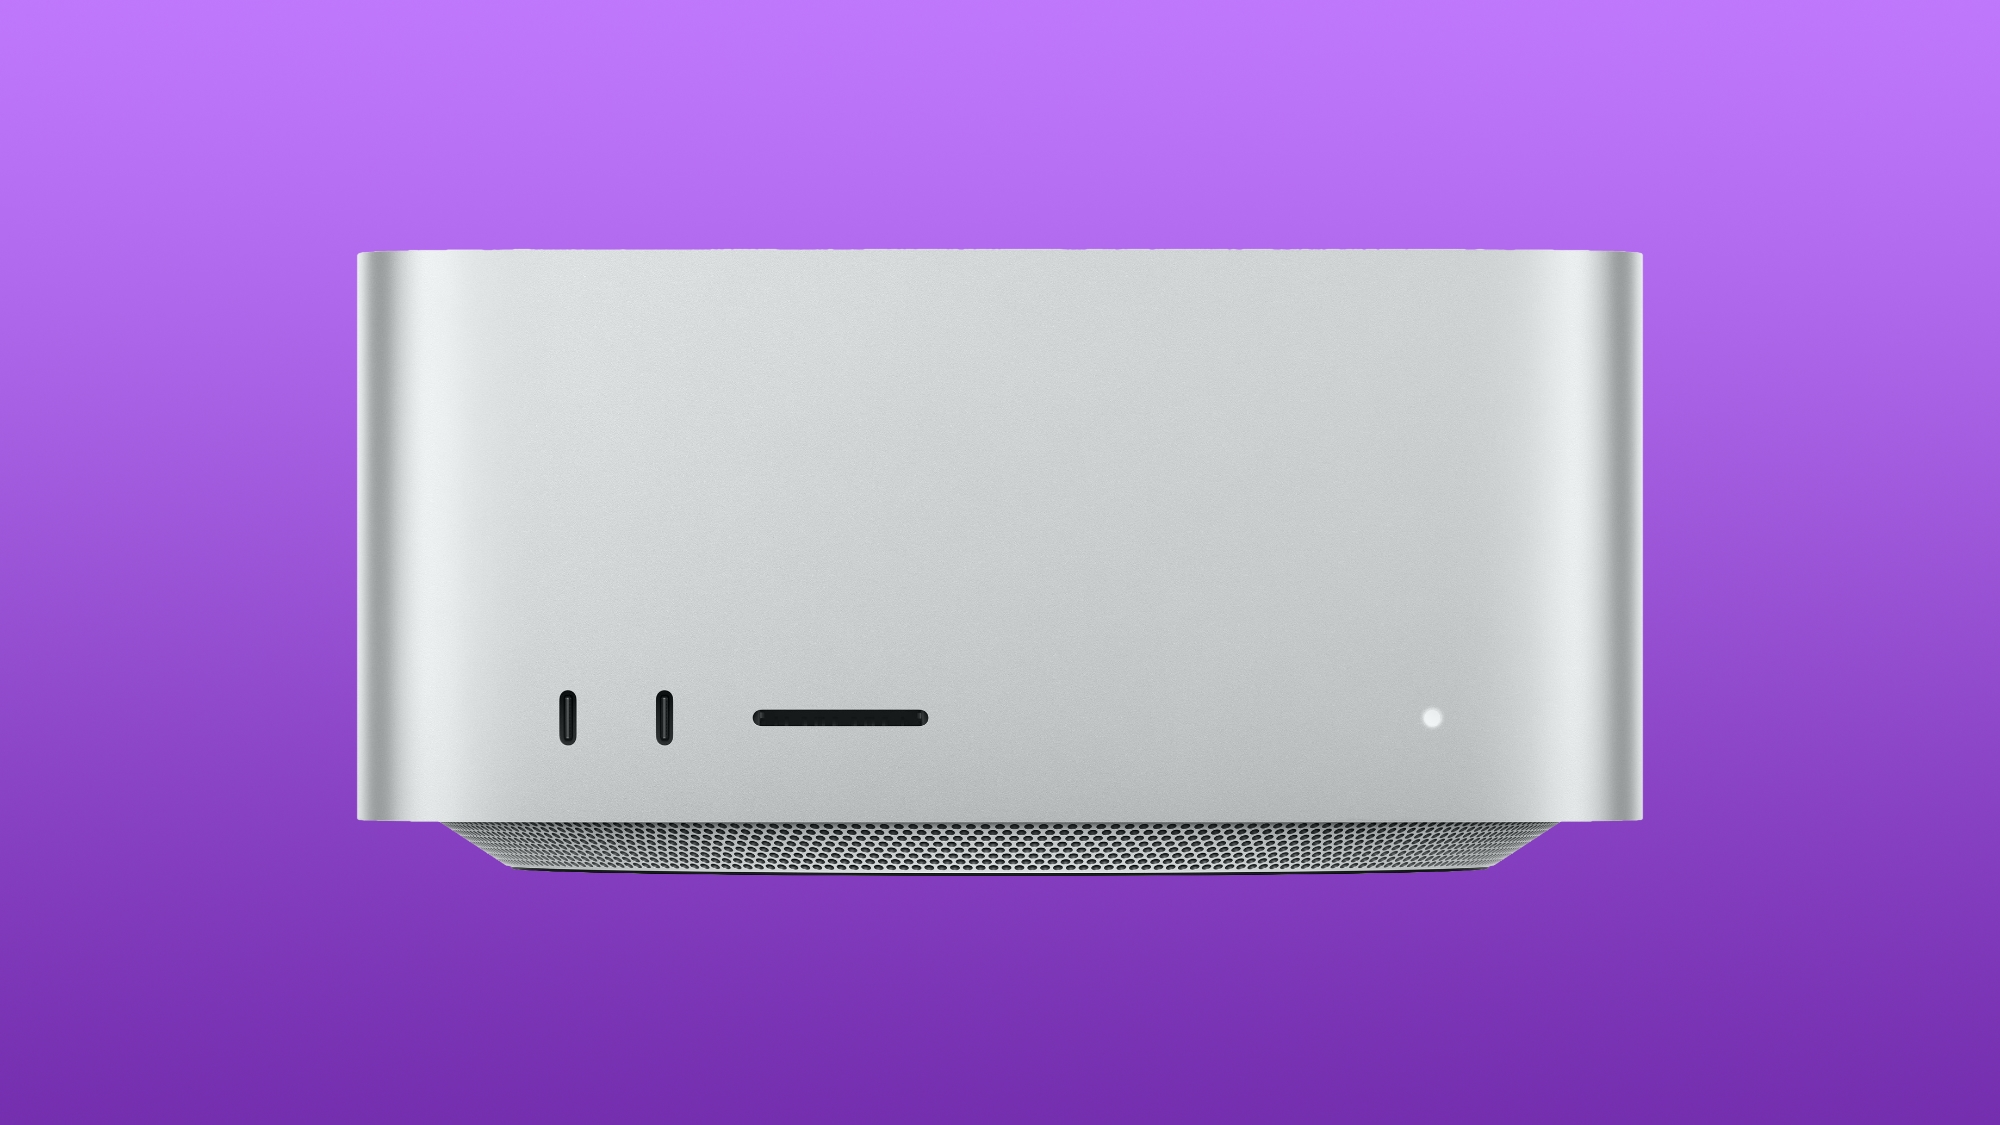
EXO Labs and Apple just killed the ‘Macs can’t cluster’ myth. Four M5 Ultra Mac Studios over Thunderbolt 5 RDMA deliver 4.8TB/s aggregate bandwidth. Here’s why latency, not bandwidth, is the real hero.
A UCLA professor used GPT to solve a decade-old math problem but couldn’t understand the AI’s compressed jargon. This reveals a growing interpretability crisis in AI.
The new M5 Ultra’s 1.2TB/s memory bandwidth is rewriting the rules for local AI inference. Here’s why the 3090 farm era might finally be over.
Leaked photos reveal Apple’s Private Cloud Compute servers packed with 32 M5 chips. Here’s what it means for on-device AI, privacy, and Apple’s competitive position.
Xiaomi’s AI Cube prototype joins three custom chips to push 1.22TB/s memory bandwidth and run 120B local models. Here’s why it matters and what’s still missing.
Hugging Face is exploring a sale at a $13B valuation. Here’s who might buy it, why it matters, and what it means for the open-source AI ecosystem.
A local Qwen 3.8 model reverse-engineered an existing script and adapted it to automate its own image prompting loop. Here’s what that means for emergent behavior in local LLMs.
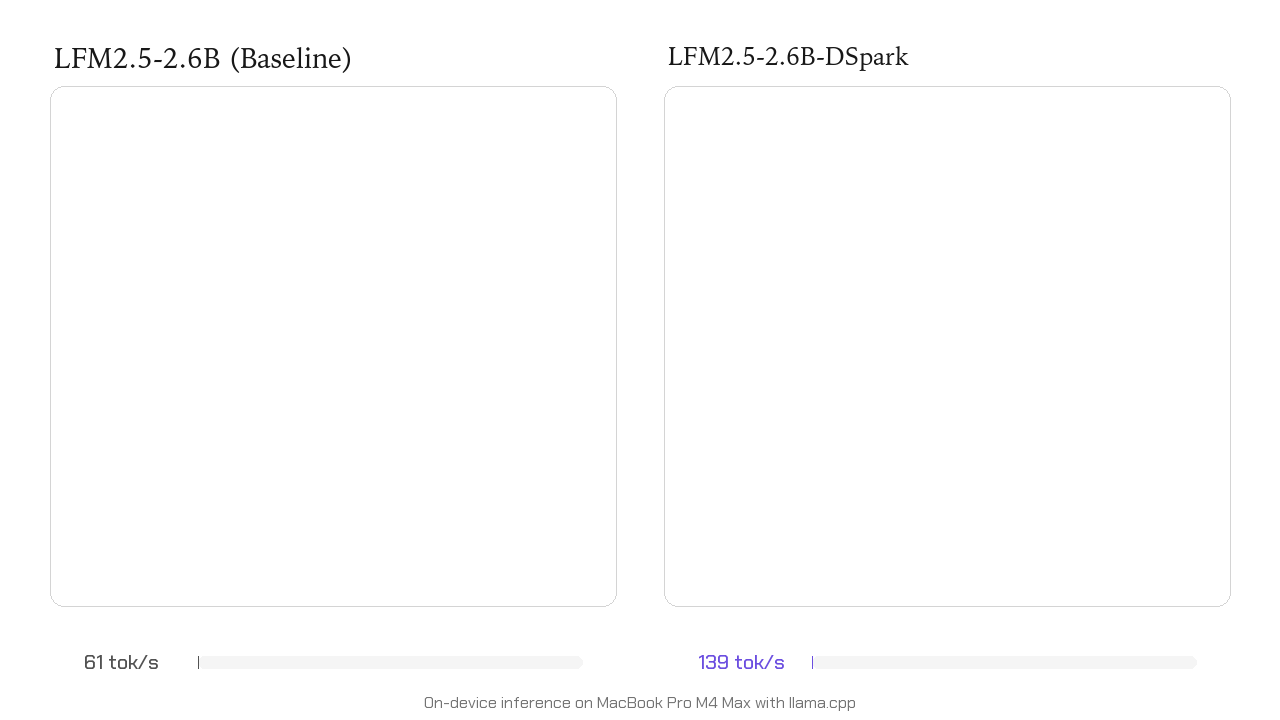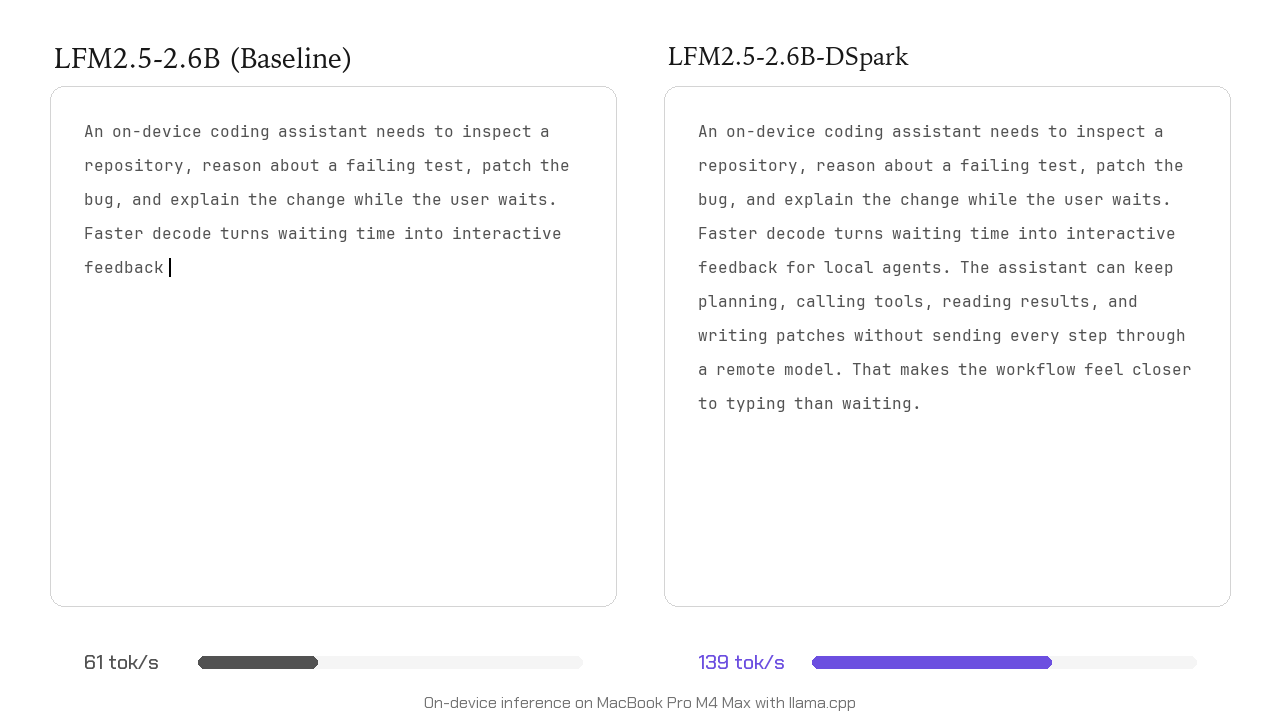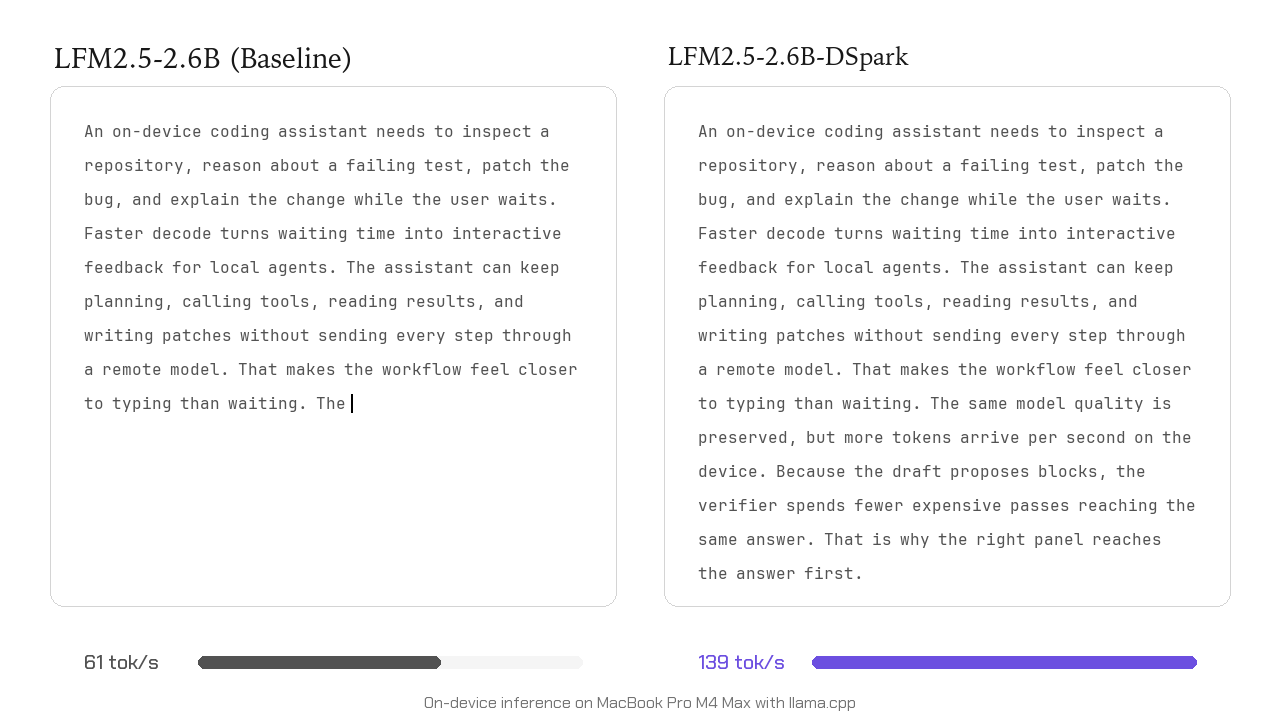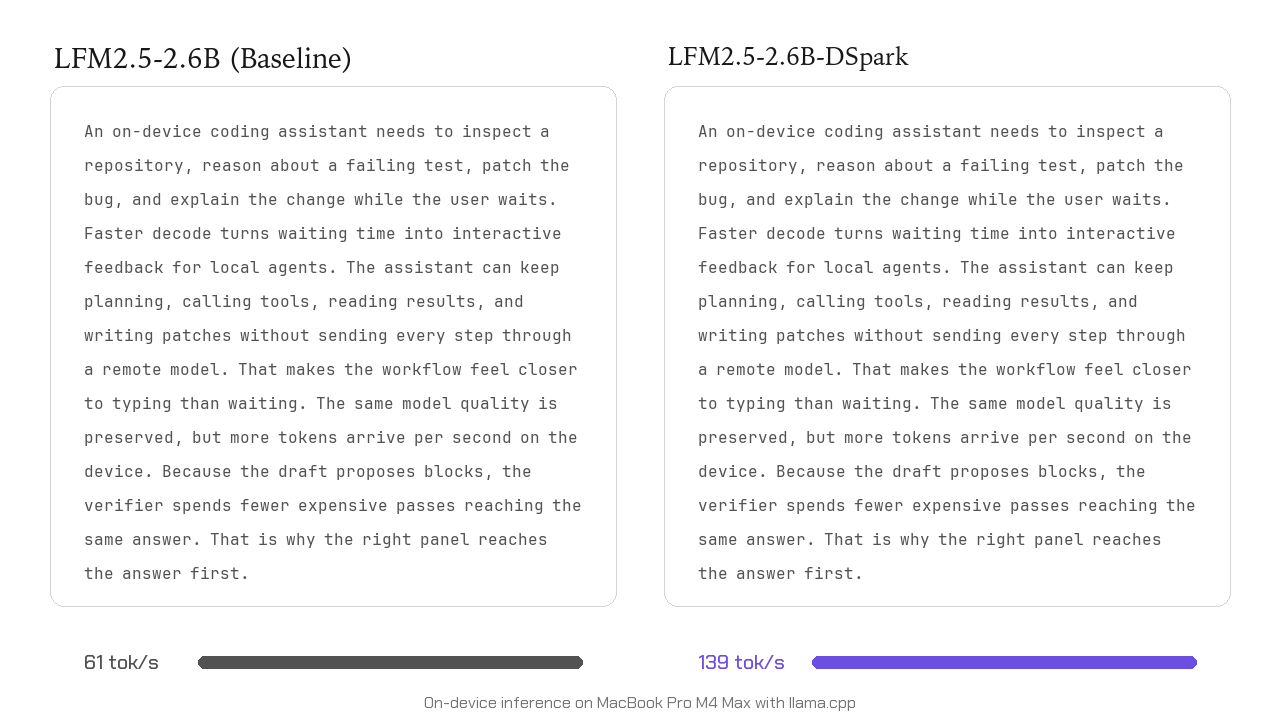
Liquid AI is teasing a 100B-parameter model that could flip the ‘bigger is better’ narrative. Here’s why speed-first architecture matters more than parameter count.
The Qwen 3.8 vs Opus debate revealed a dirty secret: the harness matters more than the model. Here’s why inference harness UX is now the real battleground.