Showing page 22 of 69
Microsoft’s clever twist on the ‘local AI’ promise forces developers to pay for GitHub Copilot, even when the models are running on their own hardware.
AIDC-AI’s new 80B parameter multimodal model uses a Mixture-of-Experts backbone to deliver superior visual reasoning at a fraction of the cost, challenging the economics of scale.
Industry data reveals companies are cutting jobs based on AI hype without seeing actual efficiency returns. Spoiler: headcount reduction isn’t ROI.
The debate over using @Transactional and @Service in your application layer gets to the core tension between architectural ideals and shipping real software.
How engineers are hacking DGX servers and RTX 4090s with water loops and power limits to make local LLMs affordable.
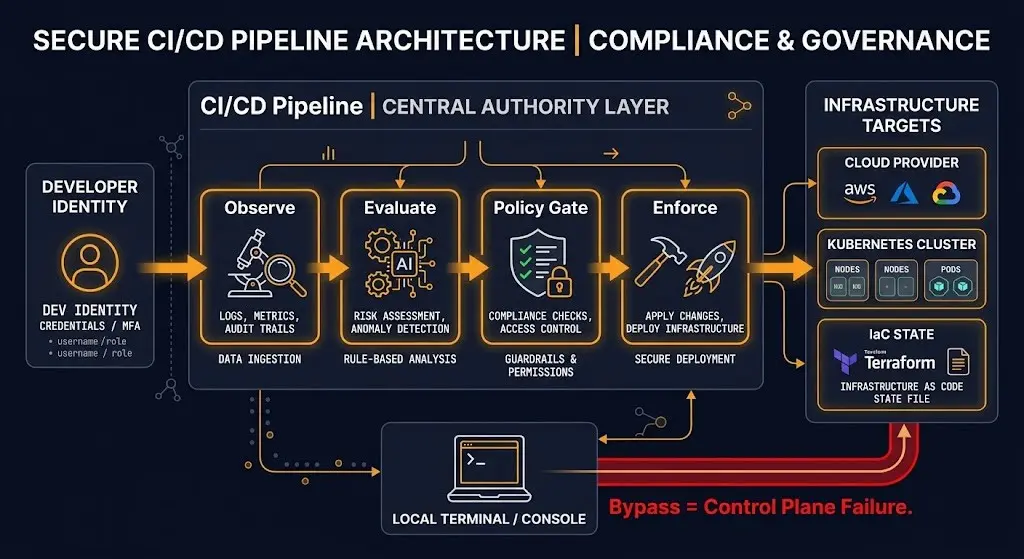
The TanStack breach wasn’t a failure of one team’s security, it was a blueprint for how trust-based development pipelines fail.
NVIDIA just dropped an experimental Rust-to-CUDA compiler that bypasses C++ entirely. The implications for safety-critical AI and distributed systems are seismic.
When your second request carries a different meaning, your ‘solved’ problem explodes. A deep dive into metadata changes, stateful failures, and the illusion of safety.
NVIDIA packs 30B, 23B, and 12B reasoning models into one checkpoint, achieving 360x training cost reduction and dynamic speed scaling.
Inside GitHub’s metered billing shift, the looming local LLM revolution, and why your laptop is becoming the most cost-effective AI server.
Elon Musk’s $4B data center lease to Anthropic isn’t collaboration, it’s a high-stakes financialization of the AI arms race.
Bun’s silent Rust rewrite hits 99.8% test compatibility, exposing the massive TCO risk hidden in your build tool’s language dependencies.