BANANDRE
NO ONE CARES ABOUT CODE

Navigation

HomeCategories

Categories

Artificial Intelligence(619)
Software Architecture(314)
Software Development(293)
Data Engineering(174)
Engineering Management(88)
Enterprise Architecture(73)
Product Management(30)
ARTIFICIAL INTELLIGENCE (619)DATA ENGINEERING (174)ENGINEERING MANAGEMENT (88)ENTERPRISE ARCHITECTURE (73)PRODUCT MANAGEMENT (30)SOFTWARE ARCHITECTURE (314)SOFTWARE DEVELOPMENT (293)
BANANDRE
NO ONE CARES ABOUT CODE

Connect

2026 BANANDRE
Privacy PolicyTermsImpressum
Built with 🍌
Page 31 of 108
ByteDance Lance Doesn’t Need 70B Parameters to Beat Your Favorite Multimodal Giant
ByteDance
Featured

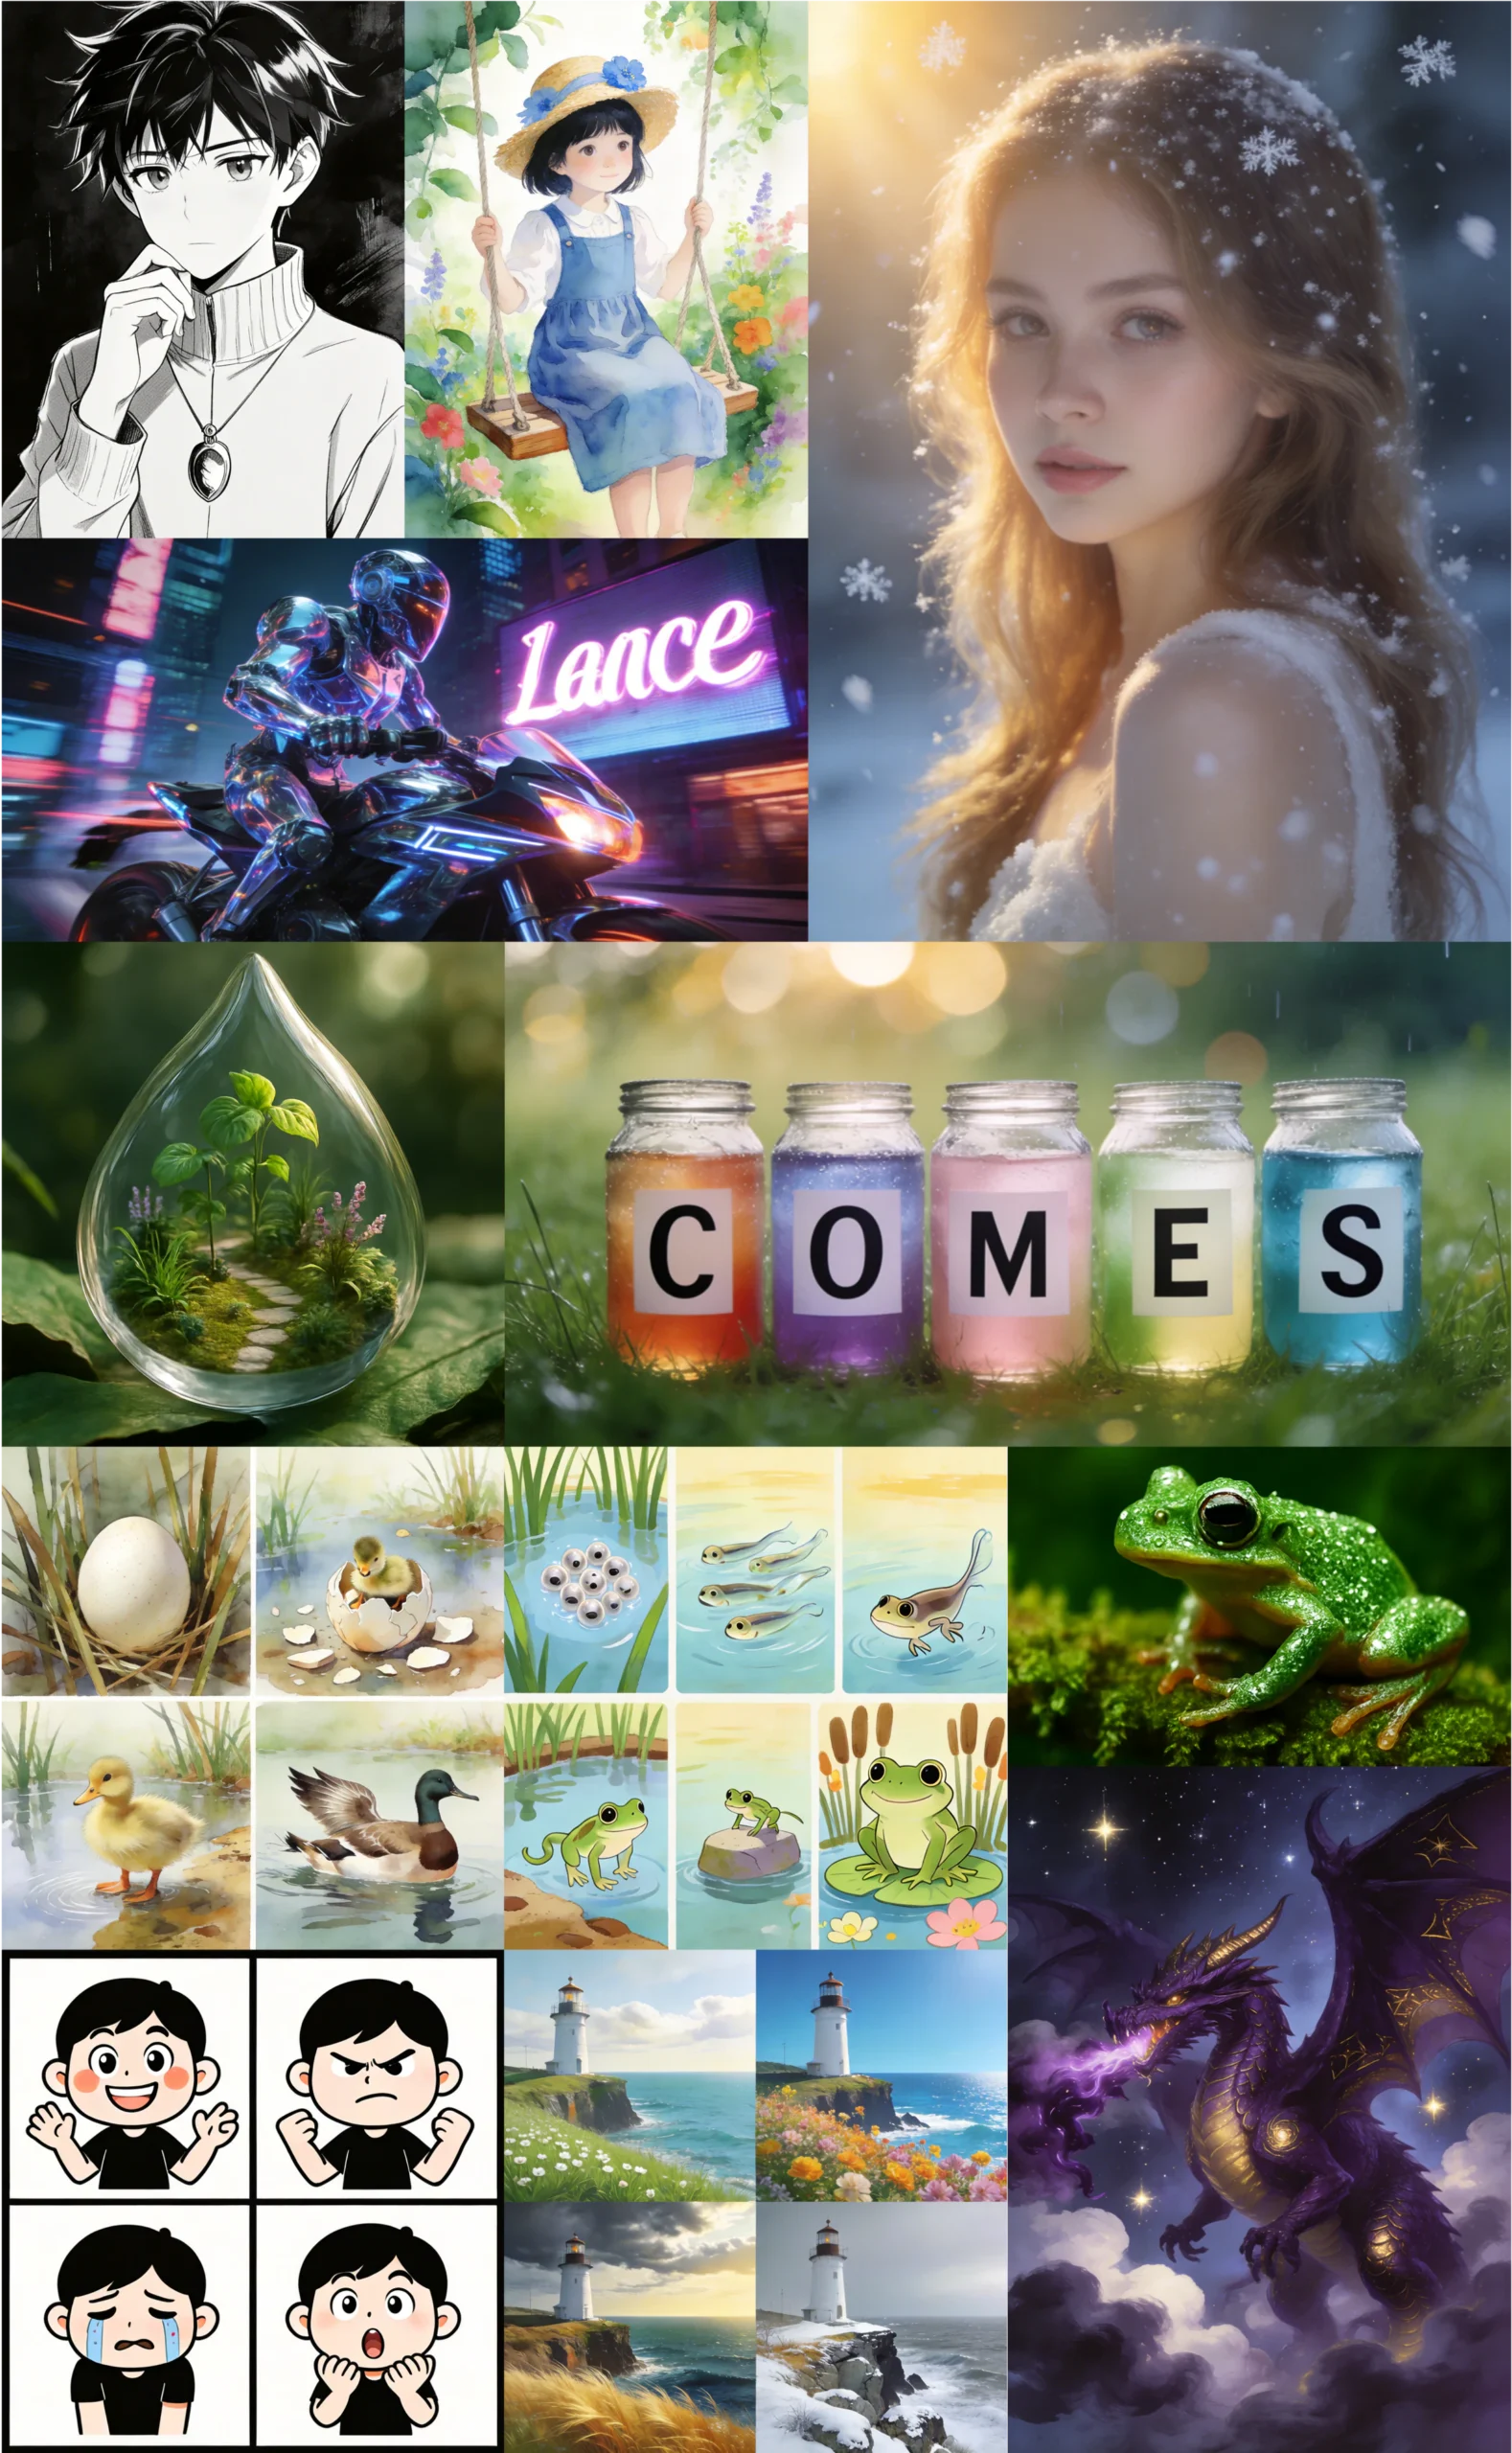
ByteDance Lance Doesn’t Need 70B Parameters to Beat Your Favorite Multimodal Giant

ByteDance’s Lance trains a unified multimodal model from scratch on 128 GPUs, proving that image and video generation doesn’t require massive scale to trade punches with 7B competitors.

#ByteDance#efficient models#lance...
Read More
The AI Backlash Hits Home: Americans Now Hate Data Centers More Than Nuclear Plants
backlash

The AI Backlash Hits Home: Americans Now Hate Data Centers More Than Nuclear Plants

A reported surge in opposition to AI and data centers, driven by energy consumption, environmental impact, and job displacement, is forcing industry leaders to address growing public skepticism.

#backlash#data-centers#energy policy
Read More
Anthropic’s Karpathy Coup: How Poaching OpenAI’s Prodigy Rewrites the AI Talent Playbook
AI Talent War

Anthropic’s Karpathy Coup: How Poaching OpenAI’s Prodigy Rewrites the AI Talent Playbook

Andrej Karpathy joins Anthropic’s pretraining team in a move that signals the AI arms race has shifted from compute scarcity to human capital warfare.

#AI Talent War#Andrej Karpathy#anthropic...
Read More
SQL Antipatterns in Fraud Detection: How to Catch Nothing and Alienate Everyone
antipatterns

SQL Antipatterns in Fraud Detection: How to Catch Nothing and Alienate Everyone

Why production fraud detection SQL collapses under its own weight, from warehouse-killing window functions to legacy sentinel values that mock your WHERE clauses.

#antipatterns#Data Engineering#fraud detection
Read More
The SaaS Authorization Trap: Why RBAC Collapses Under Multi-Tenant Reality
abac

The SaaS Authorization Trap: Why RBAC Collapses Under Multi-Tenant Reality

Multi-tenant SaaS authorization starts simple and ends in combinatorial hell. We dissect RBAC breaking points, production ABAC patterns, and relationship-aware models with real TypeScript implementations.

#abac#Authorization#Multi-tenancy...
Read More
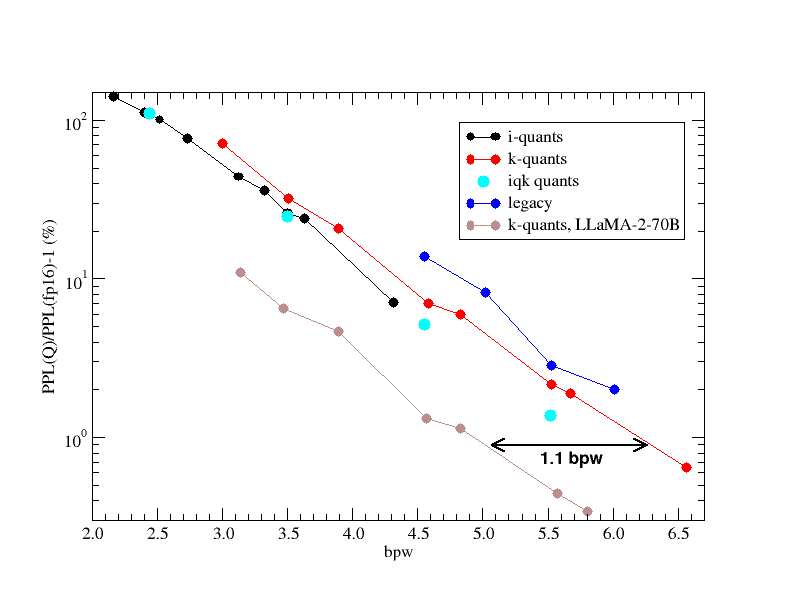
72.9 tok/s on 24GB VRAM: How ik_llama.cpp Won the Qwen 3.6 27B Backend War
ik_llama.cpp

72.9 tok/s on 24GB VRAM: How ik_llama.cpp Won the Qwen 3.6 27B Backend War

A detailed technical comparison of llama.cpp, ik_llama.cpp, BeeLlama, and vLLM for running Qwen 3.6 27B on 24GB VRAM, achieving up to 72.9 tok/s decode with specific quantizations.

#ik_llama.cpp#LLM Inference#Local LLM...
Read More
Qwen 3.7 Materialized in Qwen Chat Overnight, And the Local LLM Crowd Is Already Demanding 122B Weights
alibaba

Qwen 3.7 Materialized in Qwen Chat Overnight, And the Local LLM Crowd Is Already Demanding 122B Weights

Alibaba’s Qwen 3.7 previews appeared in Qwen Chat before anyone got a press release, sending the open-source community into a benchmarking frenzy and reviving the debate over open weights versus cloud lock-in.

#alibaba#local-ai#open-source-llm...
Read More
"The Local LLM Cost Illusion: Apple Silicon Is Slower, Hotter, and Triple the Price of OpenRouter"
"Apple Silicon"

"The Local LLM Cost Illusion: Apple Silicon Is Slower, Hotter, and Triple the Price of OpenRouter"

"A brutally honest cost analysis of running LLMs on Apple Silicon versus cloud APIs, uncovering why your $4,299 MacBook Pro is a financial trap for token economics."

#"Apple Silicon"#"cloud APIs"#"LLM"...
Read More
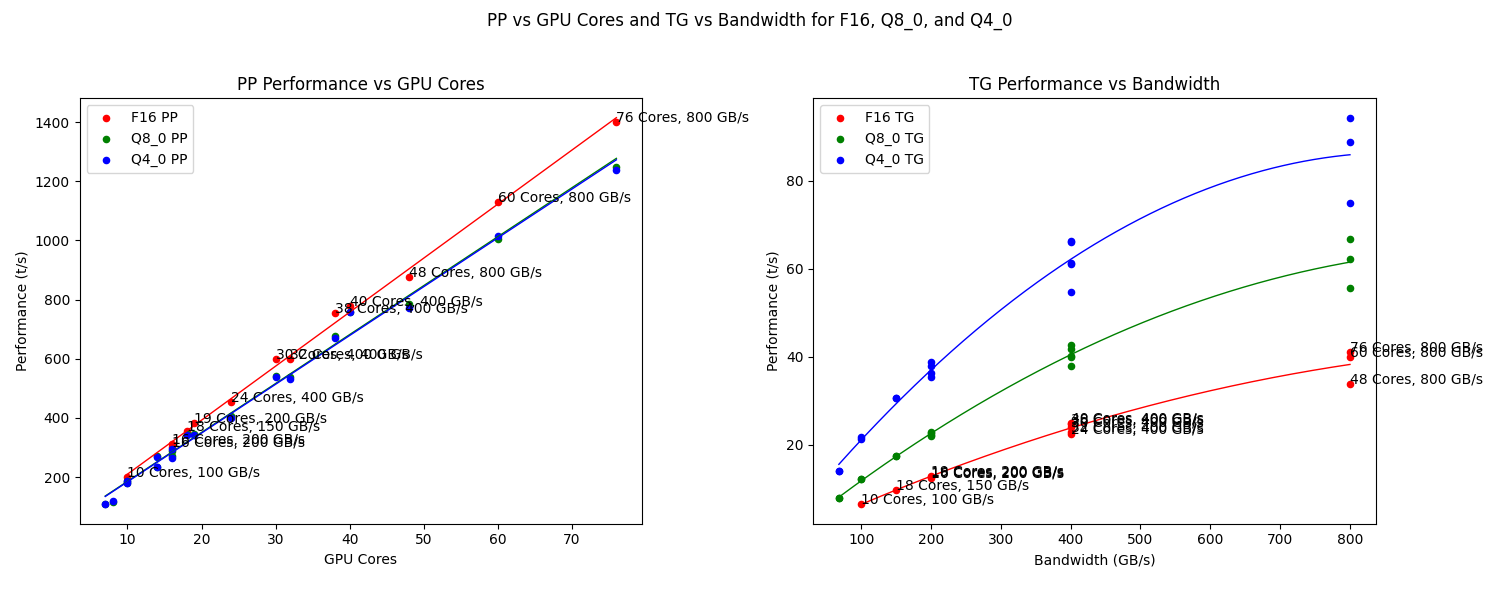
Memory Bandwidth Is the Only Spec That Matters: A Four-Way Battle Between M5 Max, DGX Spark, Strix Halo, and RTX 6000
AI Hardware

Memory Bandwidth Is the Only Spec That Matters: A Four-Way Battle Between M5 Max, DGX Spark, Strix Halo, and RTX 6000

A comprehensive head-to-head comparison of Apple M5, NVIDIA DGX Spark, AMD Strix Halo, and NVIDIA RTX 6000 across standardized tests reveals surprising price-to-performance insights, especially for the M5.
#AI Hardware#amd#apple silicon...
Read More
Abliteration Autopsy: 85 GPU-Hours of Forensics Reveal Which Safety Removal Actually Works
abliteration

Abliteration Autopsy: 85 GPU-Hours of Forensics Reveal Which Safety Removal Actually Works

An open-source toolkit compared five abliteration methods on Qwen3.6-27B. The data exposes which techniques preserve capability, which destroy it, and why one popular method is built on stolen code.

#abliteration#LLM Safety#model alignment...
Read More
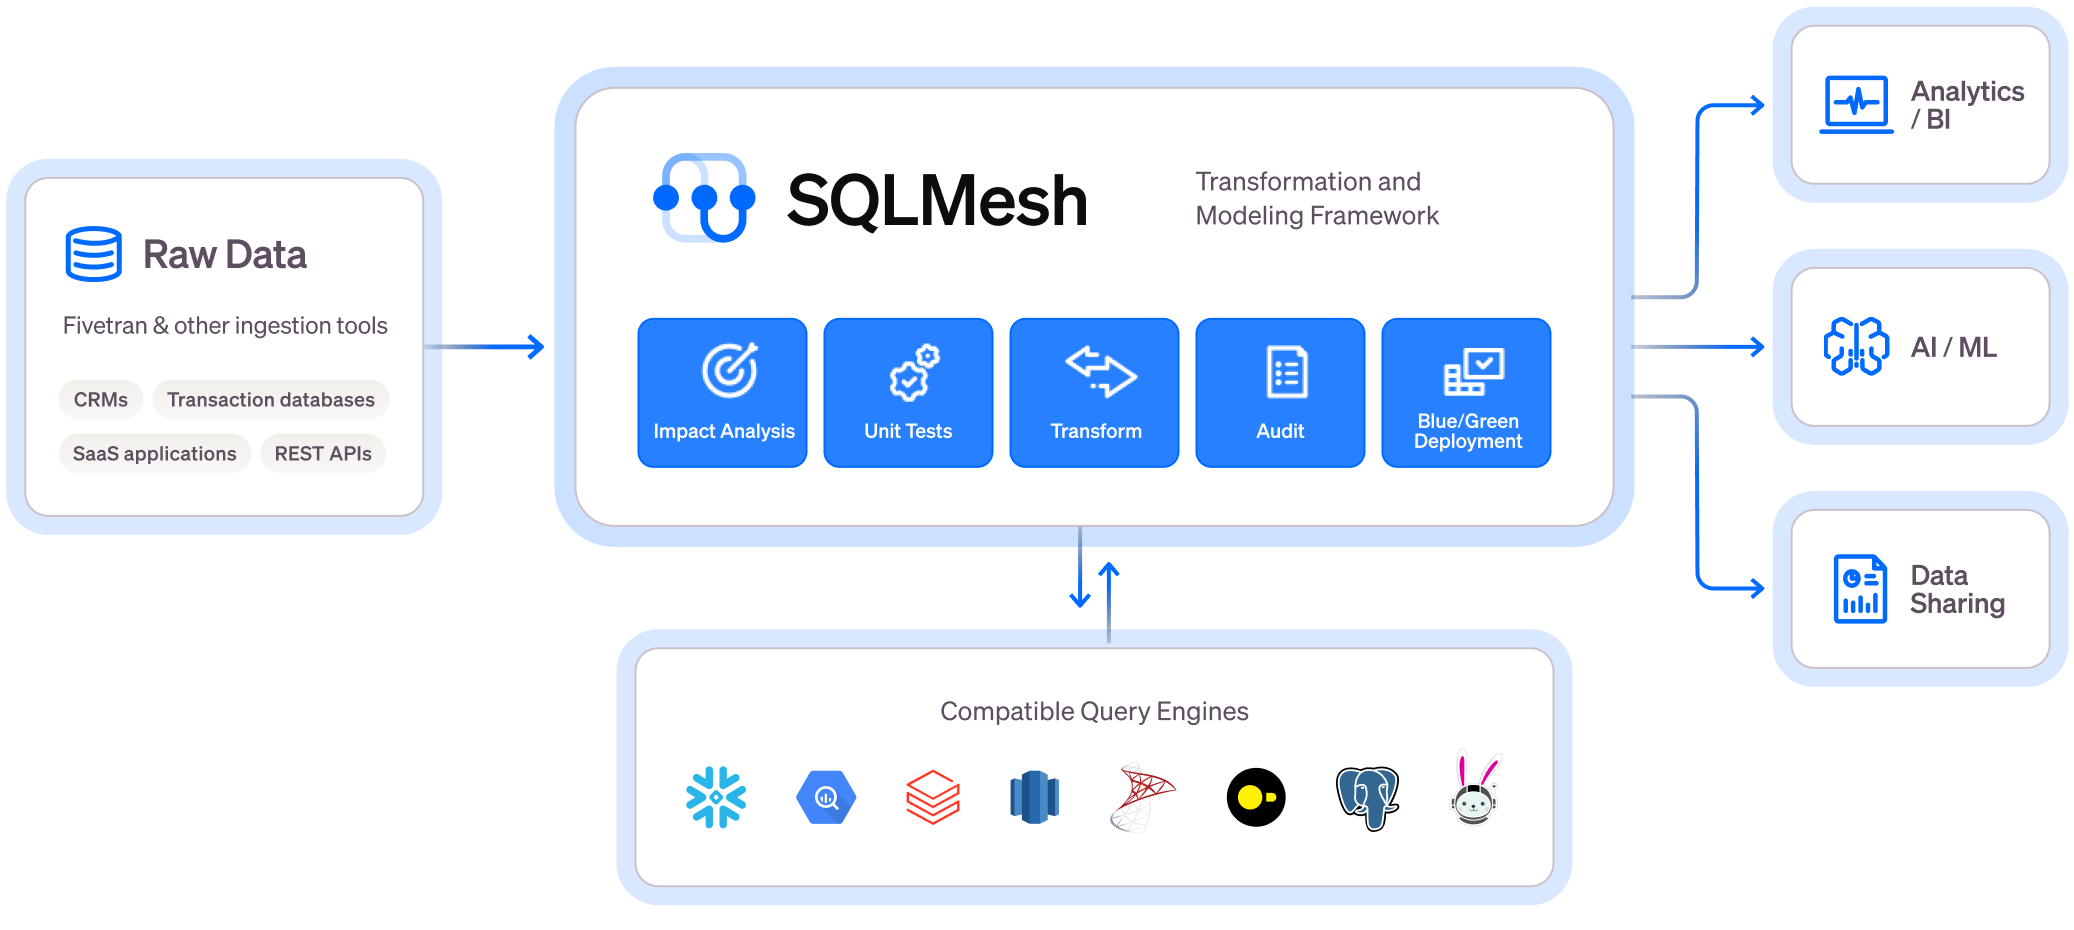
SQLMesh vs. dbt in 2026: The Challenger Stalls While the Incumbent Accelerates
Data Engineering

SQLMesh vs. dbt in 2026: The Challenger Stalls While the Incumbent Accelerates

SQLMesh’s momentum faded in 2026 while dbt shipped Fusion, swallowed the LLM ecosystem, and tightened its grip. The one feature SQLMesh still dominates might not be enough.

#Data Engineering#data transformation#dbt...
Read More
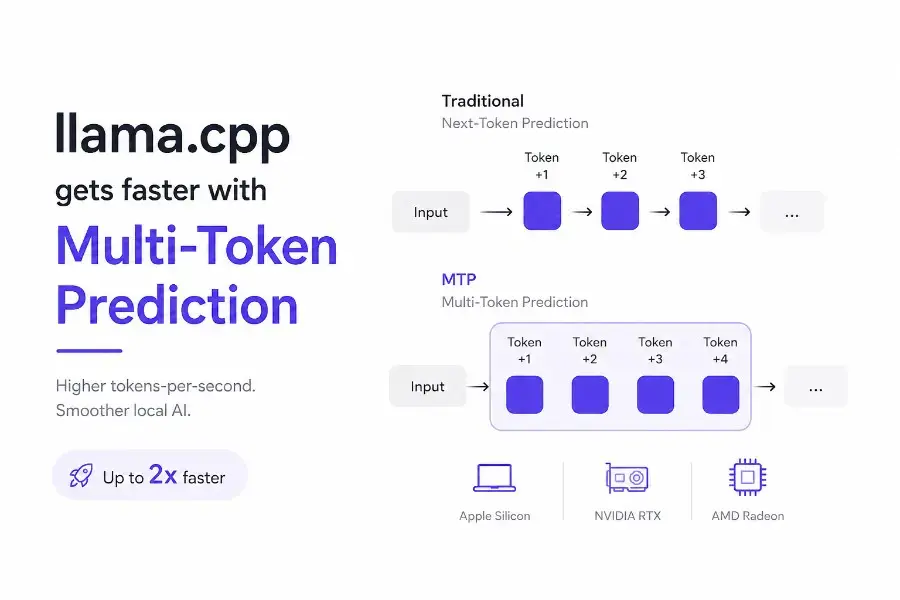
Multi-Token Prediction Lands in llama.cpp: Nearly 2Ă— Faster Generation, but Prompt Processing Is Paying the Price
Inference Optimization

Multi-Token Prediction Lands in llama.cpp: Nearly 2Ă— Faster Generation, but Prompt Processing Is Paying the Price

MTP support is now in llama.cpp mainline, delivering up to 71% faster token generation for local models. We break down the benchmarks, the prompt processing trade-offs, and how to actually enable it.

#Inference Optimization#Local LLM#MTP...
Read More
...
...