7 articles found
KRAFTON’s Raon-1 mini is a 30B MoE model trained from scratch that’s challenging AI giants on their own turf
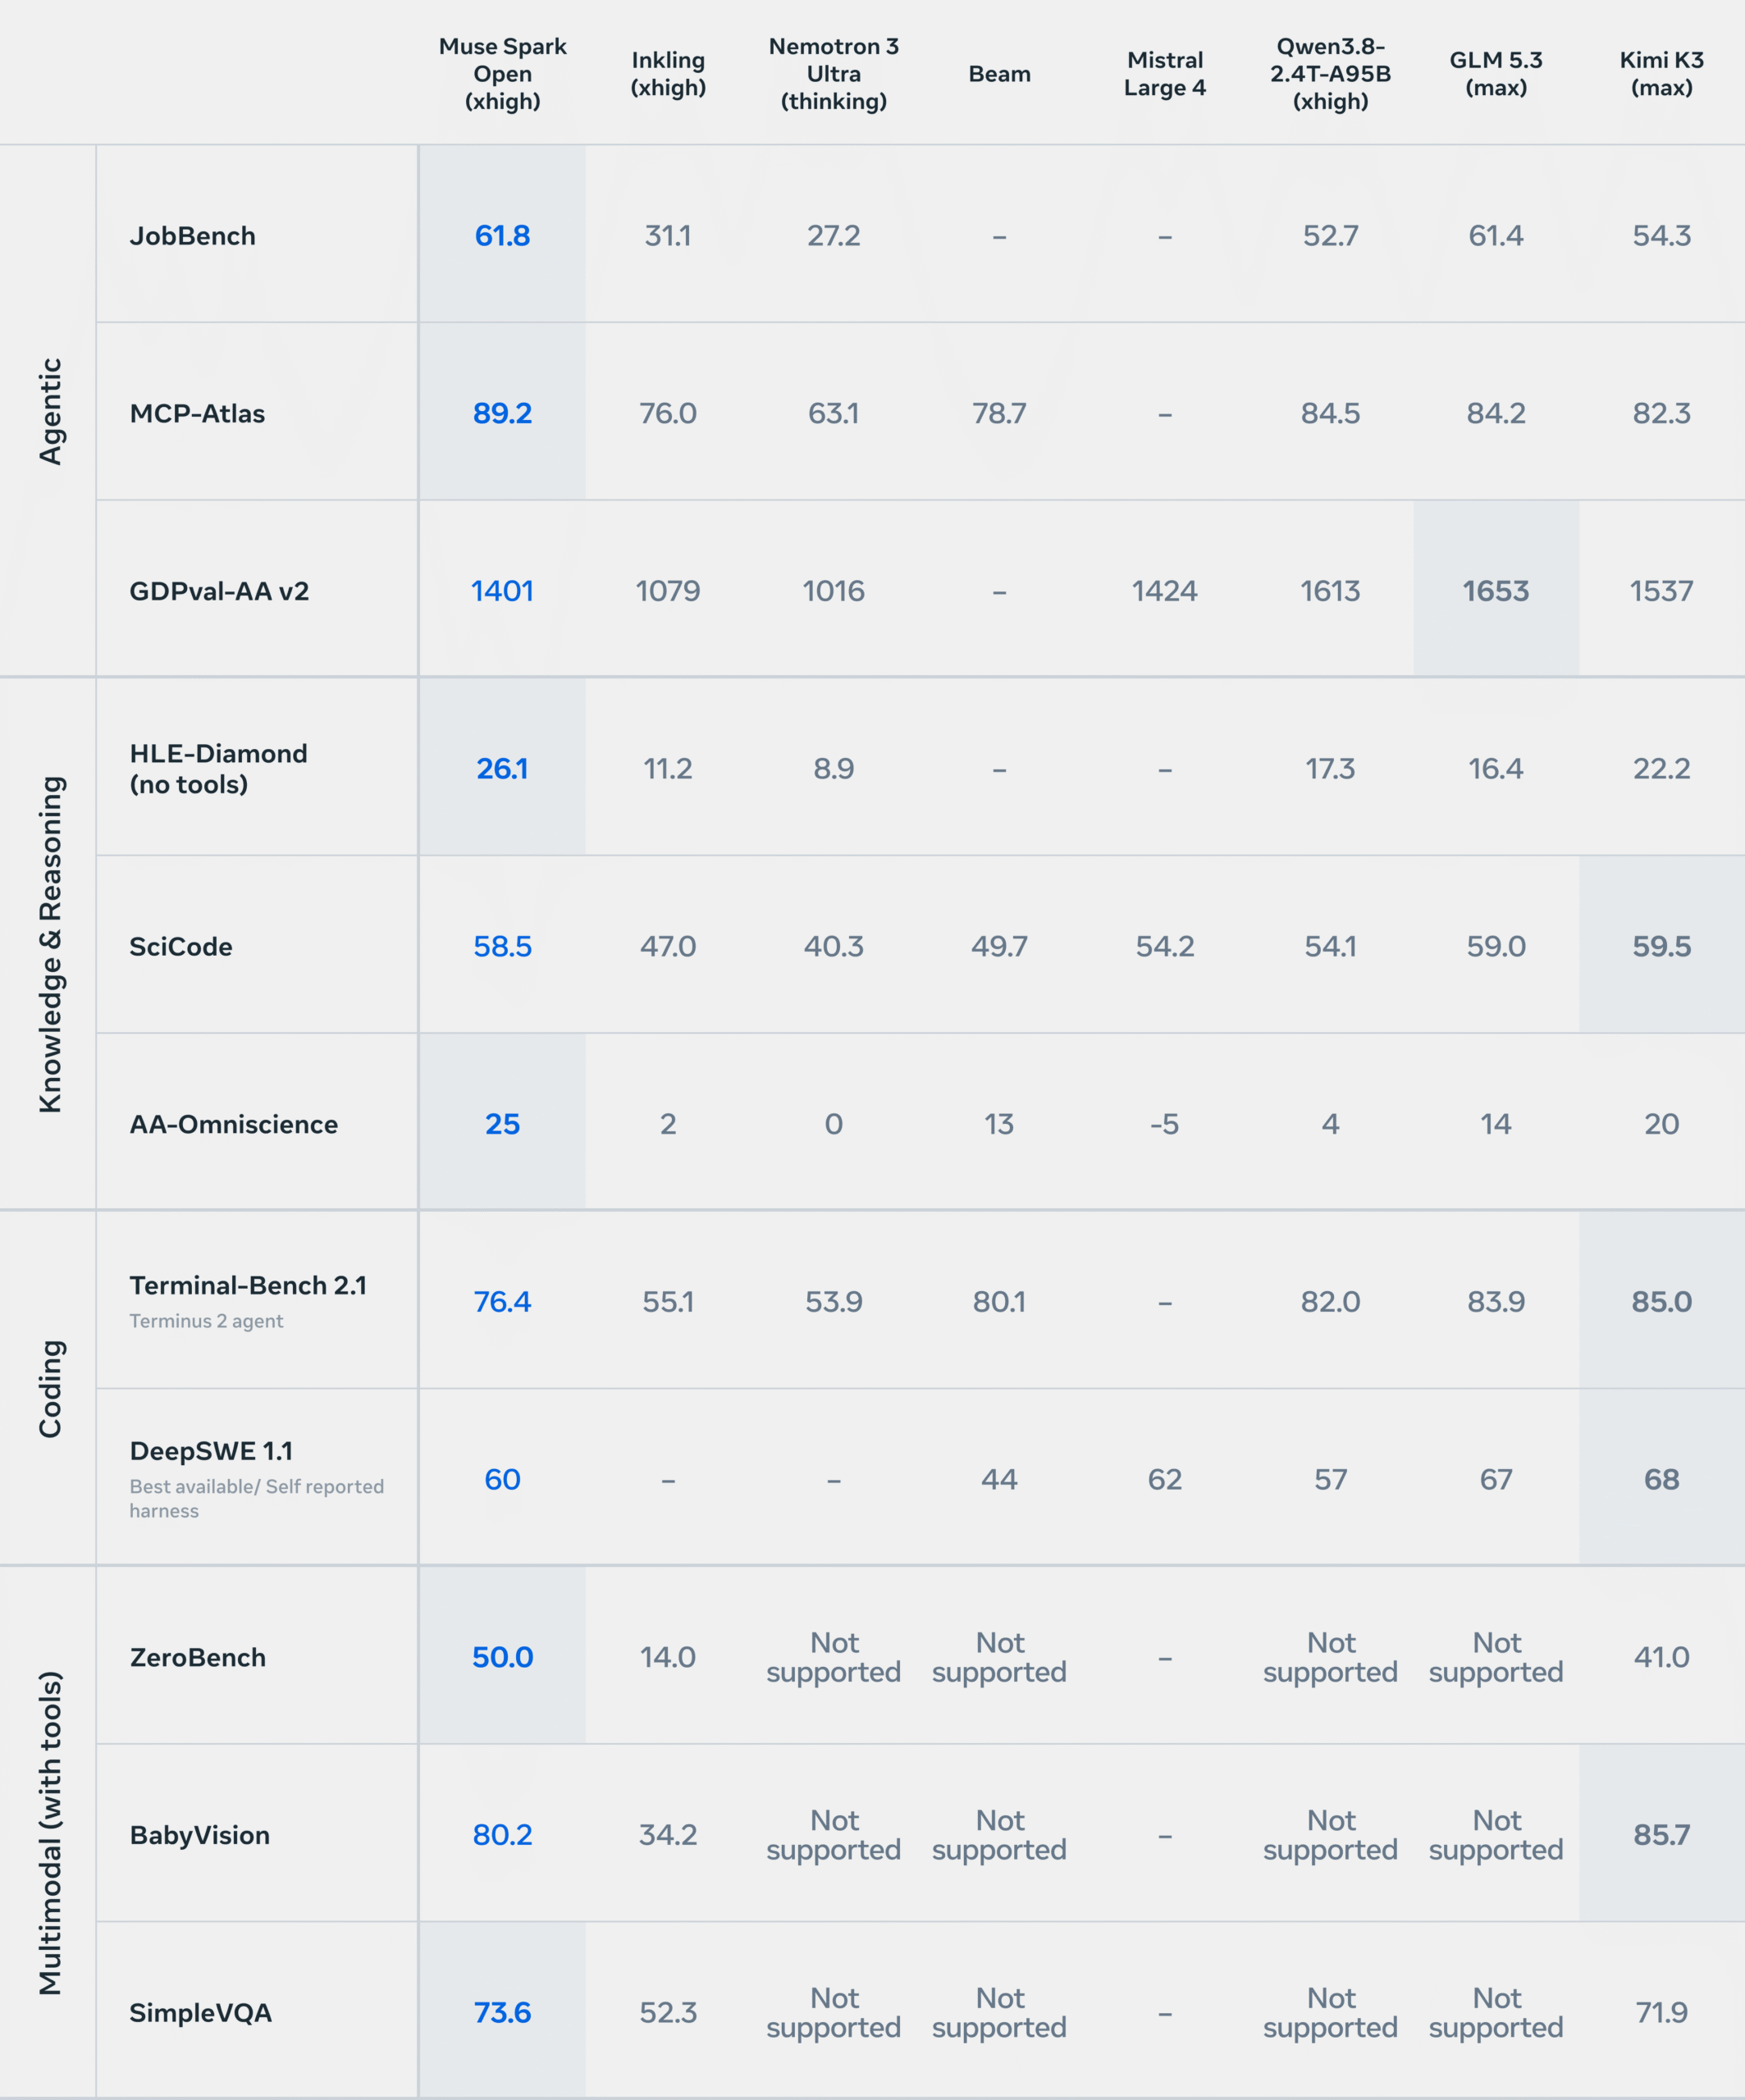
Meta’s Muse Spark Open is the most capable US open-weight model yet, but safety post-training, licensing quirks, and benchmark debates have the community split.
Aleph Alpha dropped a 78B MoE model under Apache 2.0 with a 1M token context window. Here’s what it means for enterprise AI, why the benchmarks matter, and where it falls short.
Anthropic’s incremental Opus 5.5 upgrade delivers a 40% cost cut and real performance gains, but the modular architecture debate is heating up. Here’s what enterprise teams should actually care about.
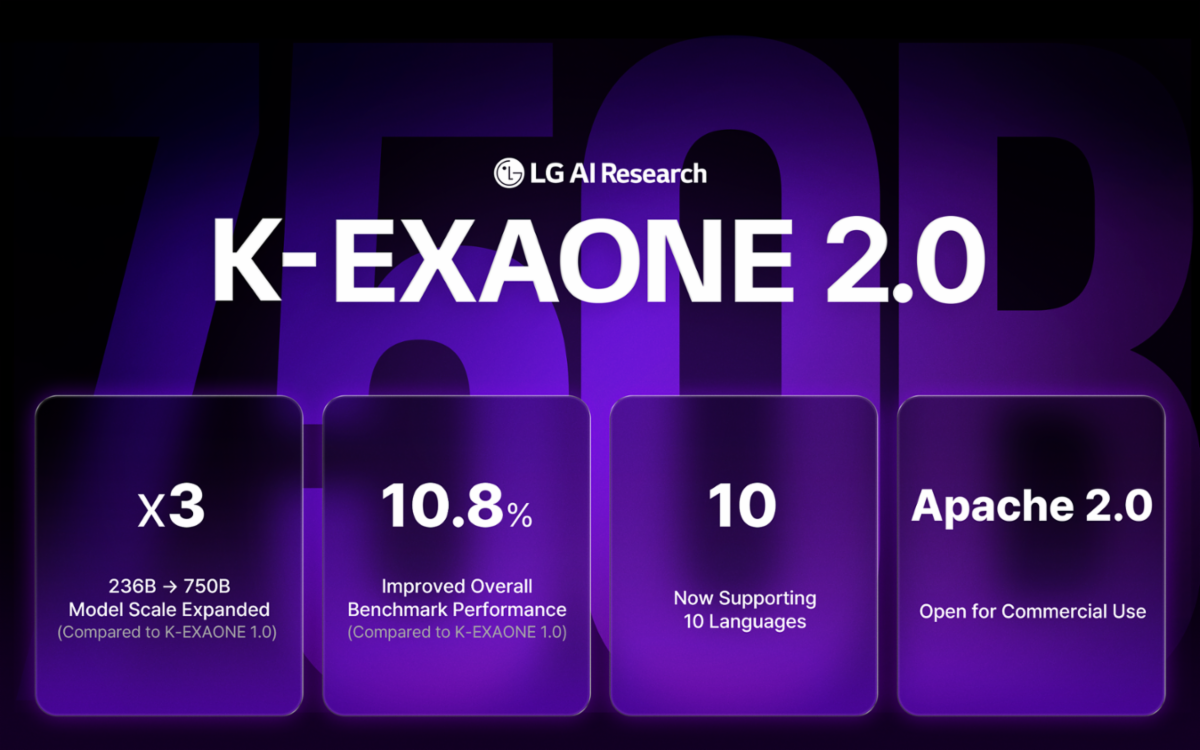
LG AI Research drops a 750B-parameter MoE behemoth under Apache 2.0. It crushes long-context benchmarks but pits 37B active params against models 10x smaller. Is this Korea’s sovereign AI win or a compute flex with diminishing returns?
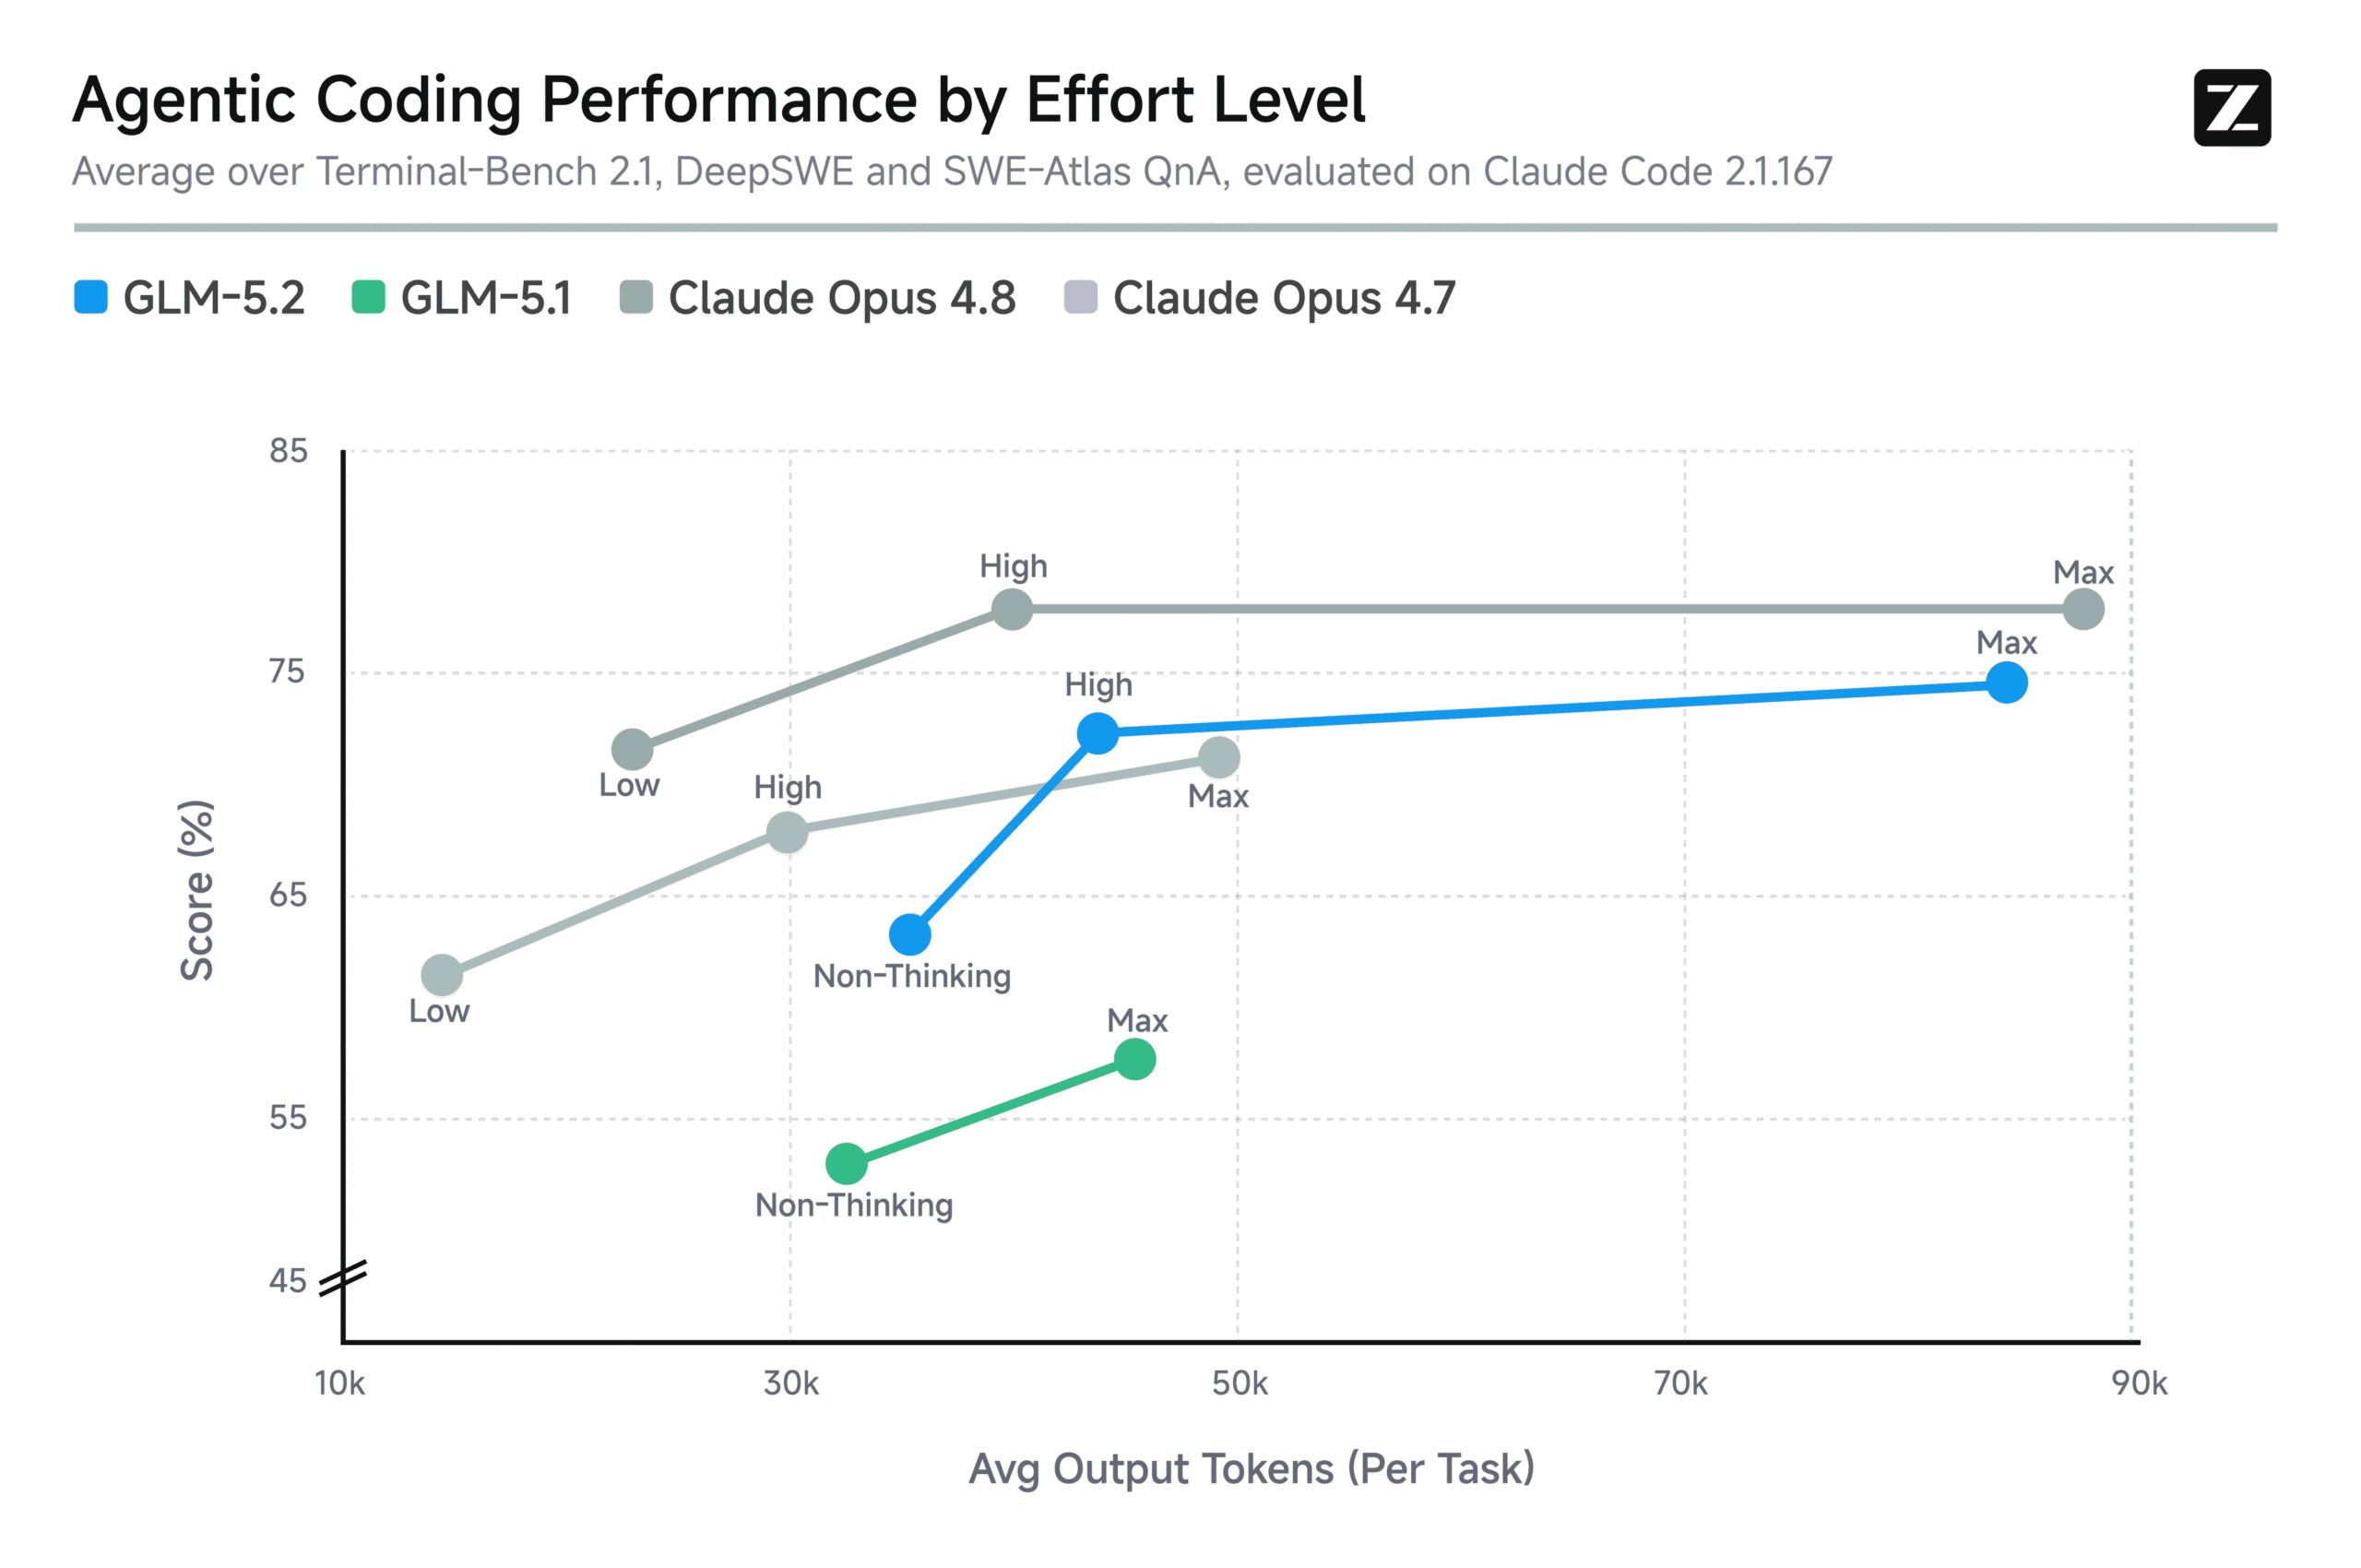
GLM-5.2 is the third-best model overall, but its MIT license means the real magic, distillation into small, local models, hasn’t even started yet.
Xiaomi’s MiMo v2.5 hits 1000 TPS on a trillion-parameter model using commodity GPUs. Here’s the deep dive on the FP4 quantization, DFlash speculative decoding, and TileRT systems alchemy that made it possible.