3 articles found
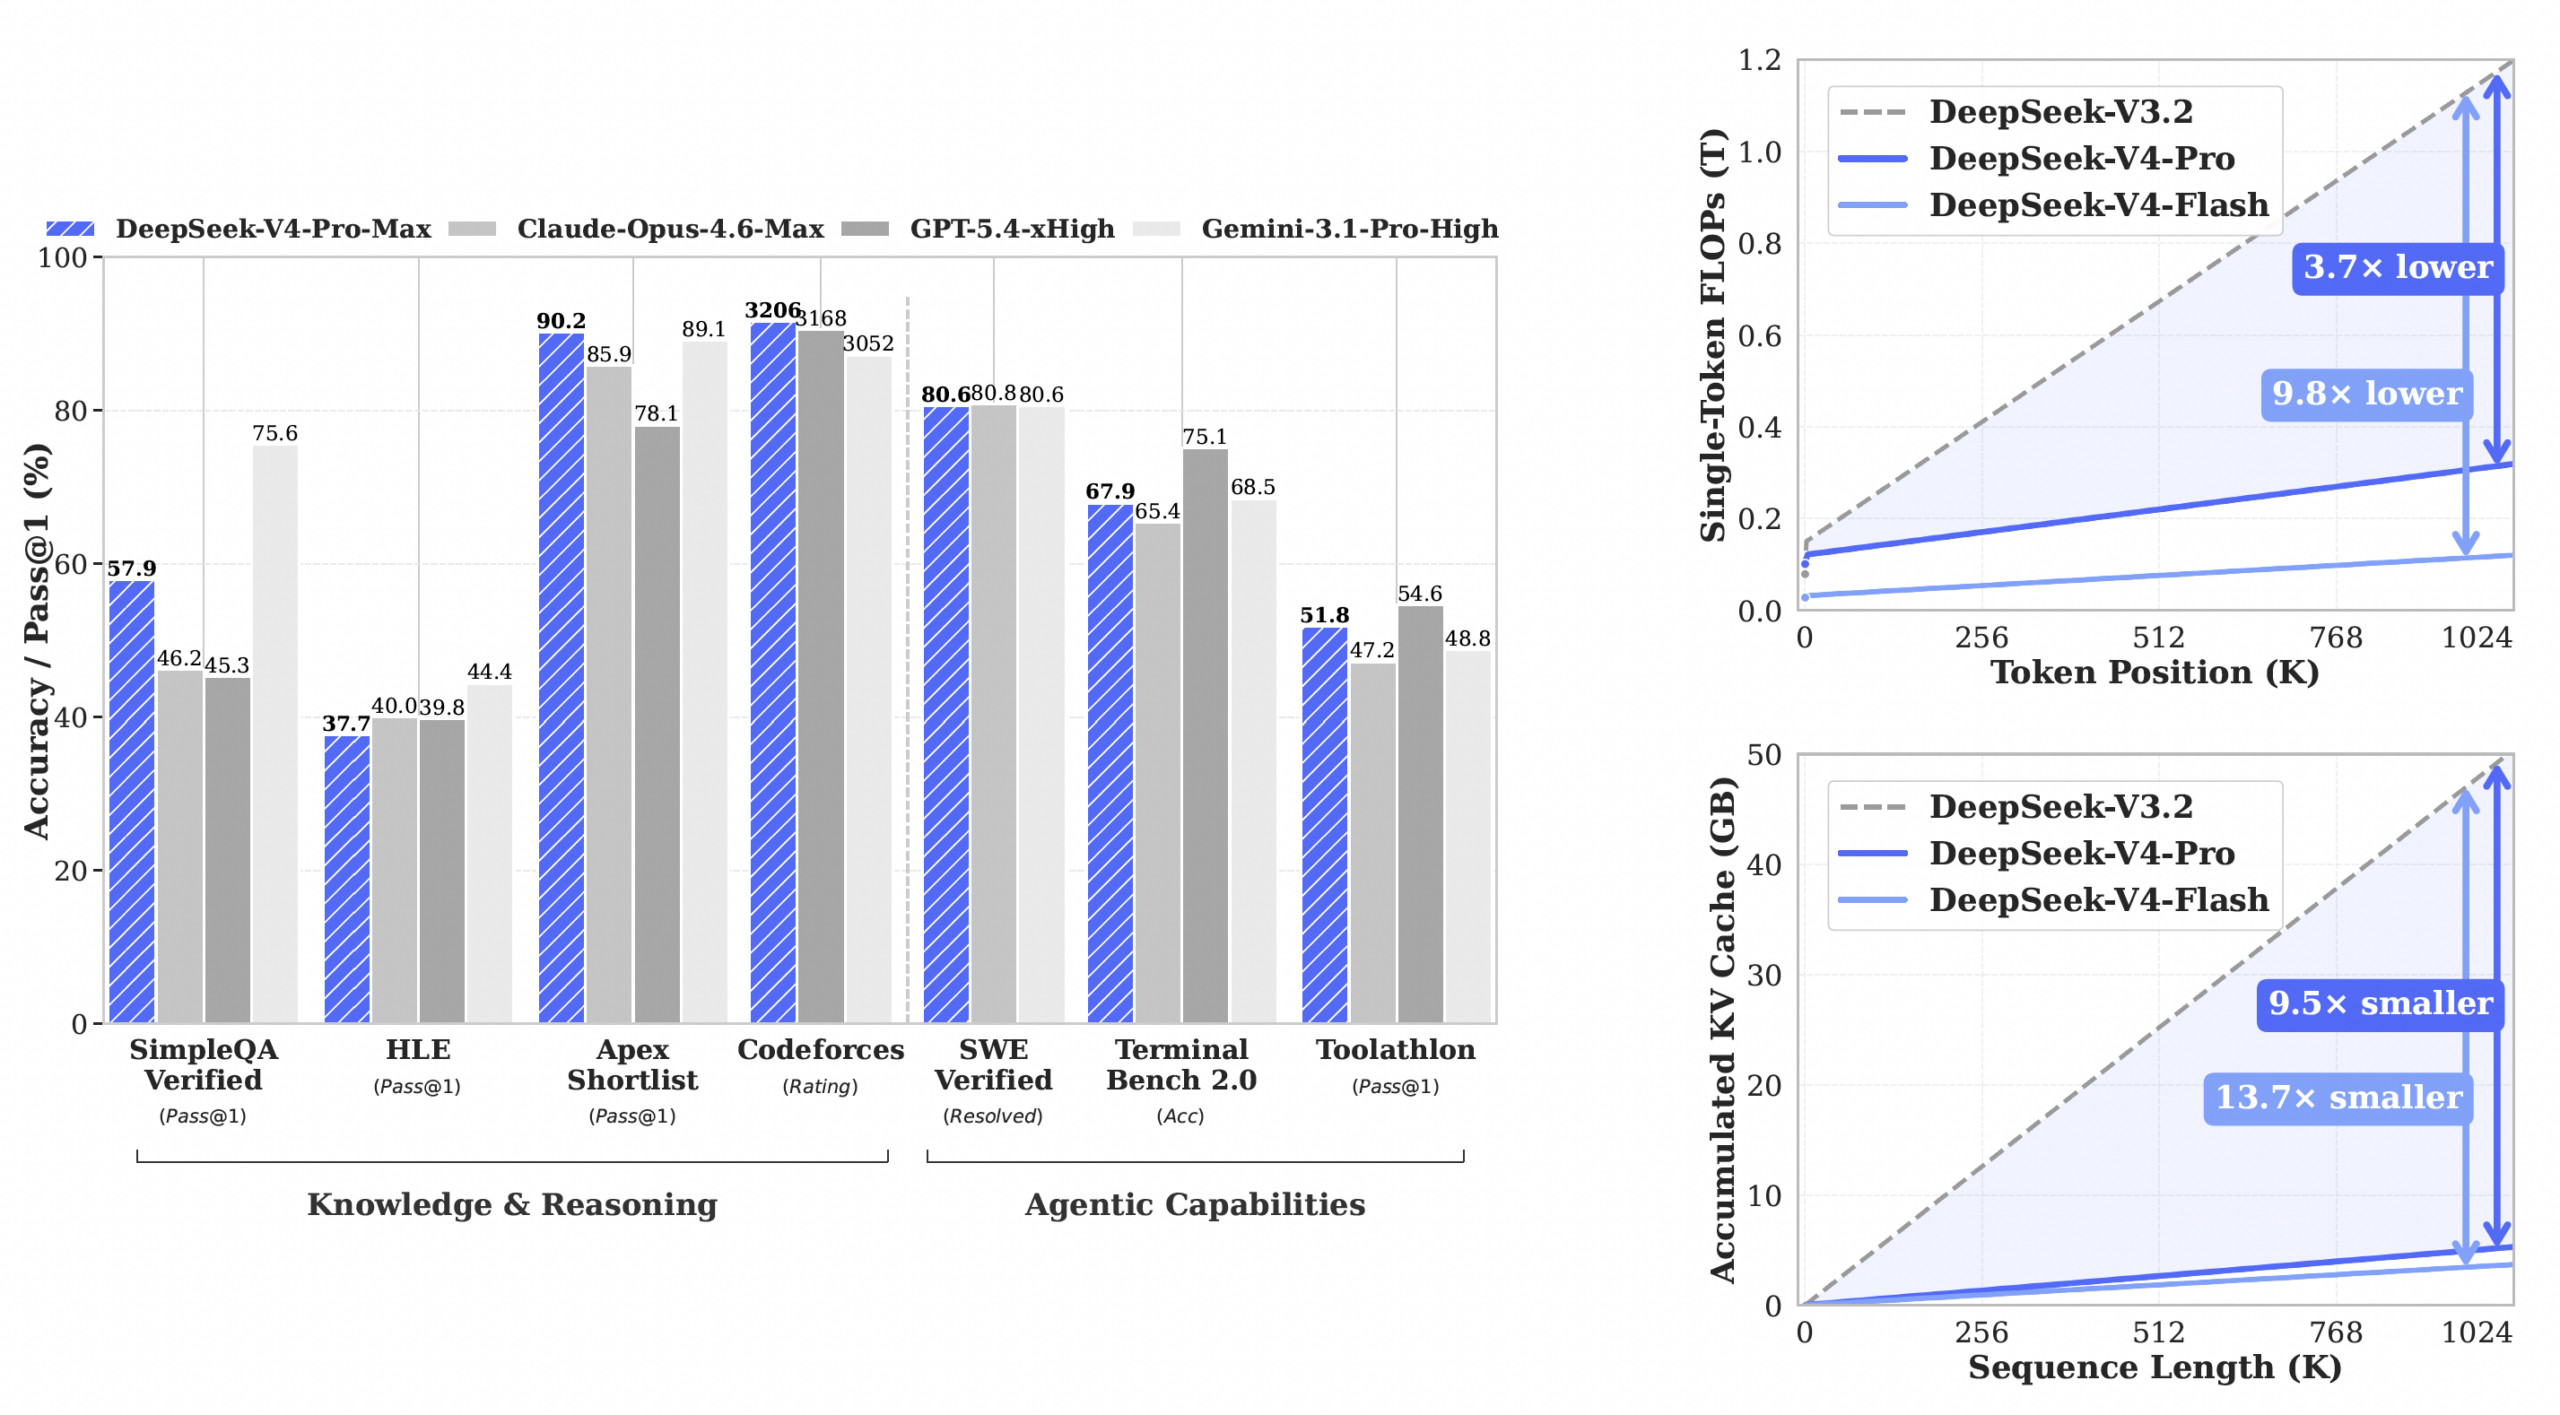
One developer got DeepSeek V4 Flash running at ~100 tok/s on four consumer RTX 3060s. Here’s how, and what it means for local AI.
Meta’s 30B agentic model runs at full 256k context on a 24GB consumer GPU. Here’s how it works, the benchmarks, and what it means for local AI.
New Triton kernels and smart packing reduce VRAM by 90% and speed up training 5x, no accuracy loss, no $10,000 GPU required.