The Token Bucket Lie: Why Your API’s Burst Tolerance Is Ruining Your Backend
Imagine this: a weather app’s backend team ships a public API with zero rate limiting. Their traffic is small, so why bother? Three weeks later, a developer building an automated dashboard writes a polling loop with no delay, hammering the /forecast endpoint thousands of times per minute from one laptop. The database connection pool exhausts in minutes. Every paying customer starts seeing timeouts.
Nobody was malicious. There simply wasn’t a mechanism to say “slow down.”
This is the exact scenario that drives teams to implement rate limiting. And the algorithm you choose determines whether your system survives the next runaway client or craters spectacularly.
The token bucket algorithm is the industry default for good reason, but it’s also the most misunderstood piece of infrastructure you’ll put in front of your API. Here’s what nobody tells you about it.
What the Token Bucket Actually Does (Without the Marketing)
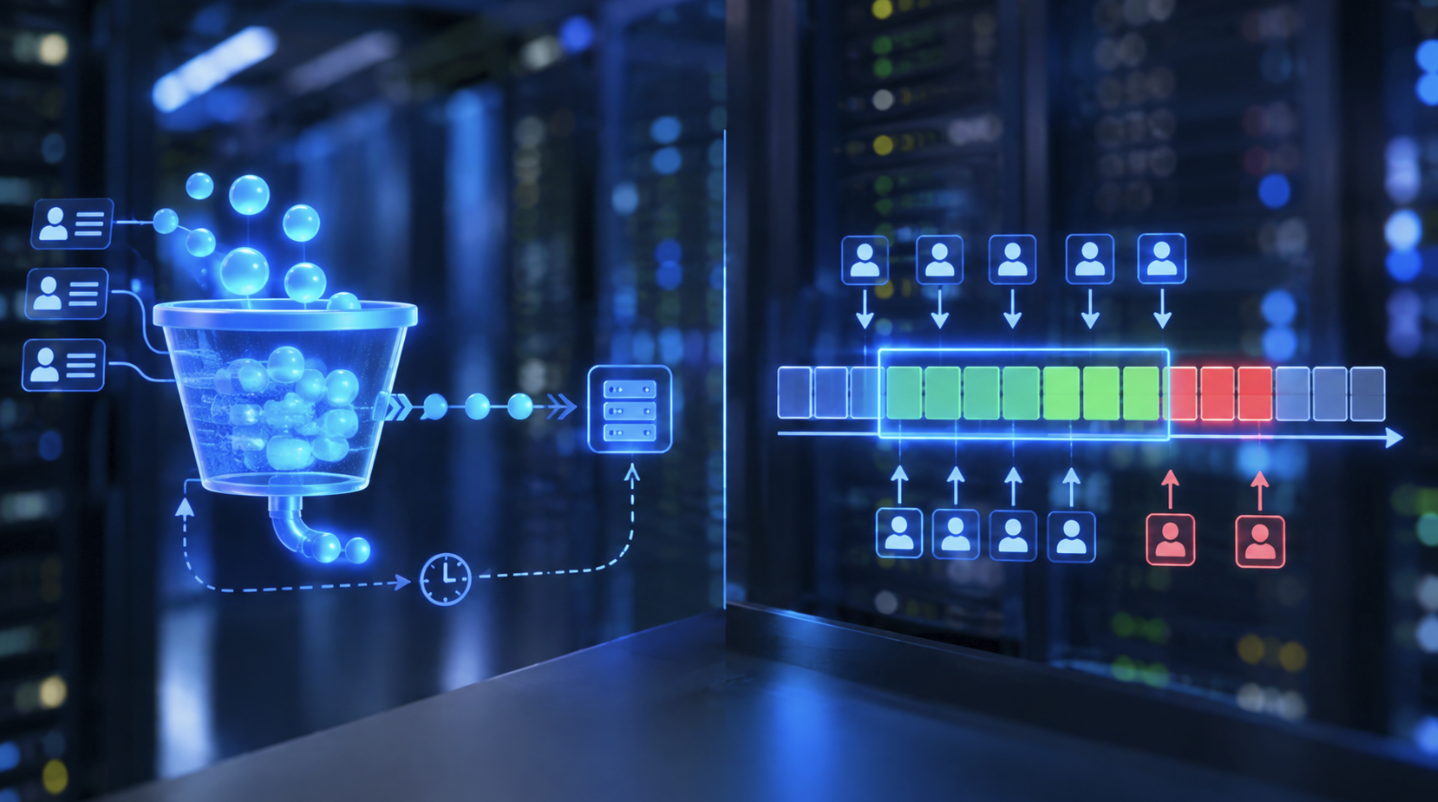
The concept is almost insultingly simple: imagine a bucket with limited capacity. Tokens drop in at a fixed rate. Every request consumes one. If tokens remain, the request passes. If the bucket is empty, the request gets rejected or delayed. When the bucket is full, tokens stop accumulating, you can’t hoard capacity forever.
Consider an API with a bucket capacity of 10 tokens and a refill rate of 2 tokens per second. A client can fire 10 requests instantly in a burst, but once depleted, it must wait for the refill pace. The burst is finite. The sustained rate is locked.
Here’s the Python implementation that appears in a thousand tutorials:
import time

class TokenBucket:
    def __init__(self, capacity: int, refill_rate: float):
        self.capacity = capacity
        self.tokens = capacity
        self.refill_rate = refill_rate  # tokens per second
        self.last_refill = time.monotonic()

    def allow_request(self) -> bool:
        now = time.monotonic()
        elapsed = now - self.last_refill
        gained = elapsed * self.refill_rate
        self.tokens = min(self.capacity, self.tokens + gained)
        self.last_refill = now

        if self.tokens >= 1:
            self.tokens -= 1
            return True
        return False
That’s it. Four properties make this elegant:
- Burst capacity is controlled independently from sustained rate via bucket size
- Smooth refill, tokens trickle back continuously rather than resetting all at once
- Low memory footprint, just two numbers per client (token count plus last refill time)
- Predictable long-term rate, throughput converges to the refill rate over any meaningful window
The burst tolerance is what separates token bucket from fixed-window approaches. A mobile app resuming from background shouldn’t be throttled because it needs five requests to refresh state. Token bucket allows exactly that spike without letting the client sustain it.
The Fixed Window Trap (and Why Everyone Falls Into It)
Fixed window counters are usually the first thing teams build and the first thing they regret. The counter resets at every window boundary, every minute, say, and rejects requests once the limit hits.
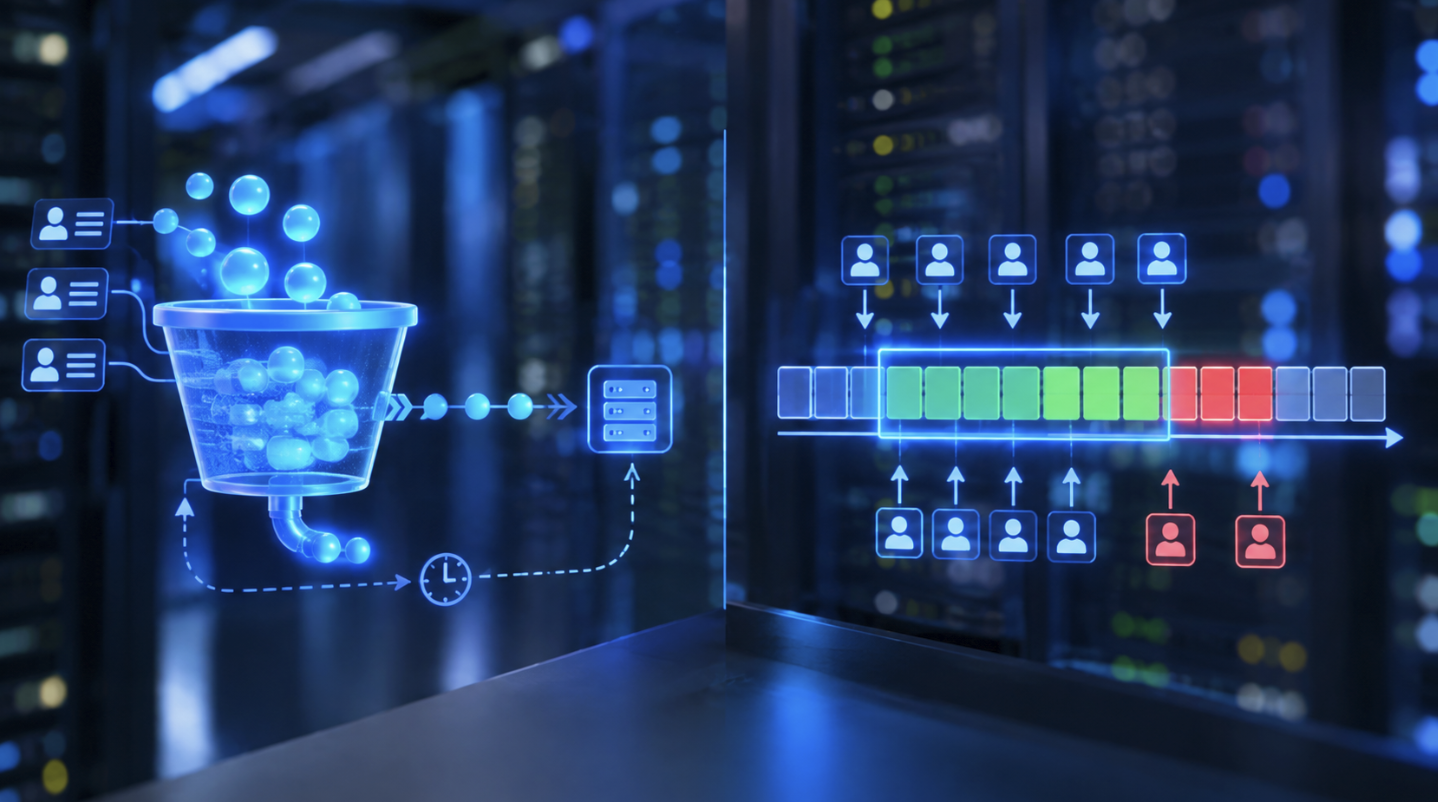
The failure mode is the boundary effect. A client can send the maximum allowed requests in the last second of one window, then send the maximum again in the first second of the next. For a limit of 100 requests per minute, that’s up to 200 requests landing in a two-second span straddling the reset.
For most API gateways, Kong, Envoy, AWS API Gateway, the fixed window’s boundary problem is well documented, which is precisely why they default to token bucket or sliding window counter variants.
But fixed window still shows up in production, and sometimes that’s fine. For coarse, low-stakes limits, a nightly batch export capped at “50 per day”, a brief doubling around midnight barely matters. The mistake is applying fixed window to protect a fragile backend resource in real time, where a short burst of double traffic is exactly what you’re trying to prevent.
Sliding Window: The Precision Alternative
Sliding window approaches count actual requests in a recent time window rather than modeling a refillable resource. The simplest version stores a timestamp for every request and discards old ones. It’s precise, never over- or under-counts, but memory-intensive at scale.
The production variant, sliding window counter, approximates this with weighted bucket counts:
def sliding_window_allowed(current_bucket_count, previous_bucket_count, elapsed_fraction, limit):
    weighted_count = (previous_bucket_count * (1 - elapsed_fraction)
                      + current_bucket_count)
    return weighted_count < limit
You trade a small amount of precision for massive memory savings. It’s why most rate-limiting libraries ship this version.
Here’s how the algorithms stack up:
| Algorithm | Burst Tolerance | Memory Cost | Best For |
|---|---|---|---|
| Fixed window | Weak at boundaries | Low | Simple policies where boundary spikes are acceptable |
| Sliding window | Better than fixed | Higher than basic counter | Fairer public API enforcement |
| Token bucket | Configurable burst capacity | Low | Bursty workflows needing short spikes |
| Leaky bucket | Smooths rather than admits | Medium | Protecting downstream systems needing steady output |
Distributed Rate Limiting: Where Token Buckets Get Ugly
The moment your service runs on multiple instances, everything changes. A bucket in one process’s memory only sees traffic through that process. Ten servers behind a load balancer multiply your effective limit by ten, possibly without your knowledge.
The standard fix is centralizing state in Redis, whose single-threaded command execution makes race-free counting straightforward. The Lua script pattern dominates:
local current = redis.call("INCR", KEYS[1])

if tonumber(current) == 1 then
    redis.call("EXPIRE", KEYS[1], ARGV[1])
end

if tonumber(current) > tonumber(ARGV[2]) then
    return 0
end

return 1
This gives every instance a consistent view of client traffic, at the cost of a network round trip to Redis on every request. For high-throughput systems, teams shard the Redis layer or accept eventually-consistent local approximations.
One practitioner put it well: Redis with a Lua script for the atomic check-and-consume prevents race conditions when multiple instances hit the same key. Fail open is tempting but dangerous, a stampede during an outage can take down everything behind the limiter. Their approach: fail closed on public endpoints, fail open on internal ones where availability matters more than protection.
This mirrors distributed rate limiting architectures and real-world pitfalls of naive rate limiting implementations in ways that only become obvious after your first 2 AM incident.
The Failure Modes Nobody Warns You About
A rate limiter is infrastructure, and infrastructure fails in predictable ways:
The limiter becomes the bottleneck. If every request makes a round trip to centralized Redis before proceeding, and that Redis is under-provisioned or in another availability zone, you’ve added latency to every request, including the ones you allow through. Teams respond by co-locating the store with the application tier, batching Redis calls, or accepting relaxed local approximations.
Clock skew breaks window-based systems. Servers disagreeing about window boundaries create inconsistent enforcement. Token bucket implementations reduce this problem because they track elapsed time rather than calendar boundaries.
Spoofable limit keys provide zero protection. Rate limiting by a header clients can trivially modify is theater, not security.
Retry loops create feedback spirals. A client hits the limit, retry logic fires immediately, and the retries themselves keep the client permanently rate-limited. The solution is exponential backoff with jitter, doubling the wait after each failure, with randomization so all clients don’t retry simultaneously.
Then there’s the subtle one: a token bucket prevents sustained overload, but it doesn’t stop a distributed denial-of-service attack. That needs CDN or DDoS mitigation upstream, before traffic ever reaches your limiter.
Choosing Limits Per Endpoint (or Not)
Applying one global rate limit across an API signals you haven’t thought through your strategy. Different endpoints have wildly different costs:
- Authentication endpoints: tight per-IP limits to slow credential stuffing, layered with account lockout logic
- Search or query endpoints: moderate limits, computationally expensive even though they’re reads
- Write endpoints: strictest limits, each request triggers database writes or cache invalidation
- Bulk or export endpoints: separate, low limits with longer windows
Some teams formalize this with cost-weighted quotas. GitHub’s GraphQL API uses points-per-minute, letting clients spend faster on expensive calls. It’s more work than flat limits, but it avoids the situation where clients track a dozen separate quotas for a dozen routes.
Tiered limits by client type, free, paid, internal, are also common, keyed by API key or account rather than IP. IP-based limiting breaks down for clients behind shared NAT gateways or corporate proxies.
The Real Controversy: What Happens When Redis Dies
Here’s the question that starts fights in architecture reviews: do you fail open or fail closed when your rate-limiting store goes down?
Fail open means allowing all requests, you risk overload during the exact moment your limiter would have helped. Fail closed means rejecting all requests, you risk a full outage over what should have been a soft-limiting mechanism.
The production answer is nuanced. Fail closed on public endpoints where protection matters most. Fail open on internal service-to-service calls where availability trumps strict enforcement. But there’s a critical distinction that gets missed: surviving the rate limiter is not an authorization decision.
One security engineer made this point emphatically: a token bucket answers how many calls a client may make right now, not whether this actor may perform this action on this resource. The authorization check still runs in the handler, with subject, action, resource, and tenant context. The bucket is keyed on the authenticated principal, not a client-supplied ID, so one tenant can’t burn another’s budget or hide behind a shared IP.
Failing closed on the limiter is a capacity choice. Failing open on the authz check is a different bug. Don’t collapse those two fallbacks into one decision.
Client-Side Responsibility (The Part Everyone Skips)
Rate limiting only works if clients respond sensibly. A well-designed API signals clearly: HTTP 429 with a Retry-After header tells a well-behaved client exactly how long to wait.
But there’s more. APIs that expose remaining-quota headers (X-RateLimit-Remaining, X-RateLimit-Reset) give clients enough information to self-throttle before hitting the hard limit. That reduces rejected requests and creates a dramatically better integration experience, clients discover limits through documented headers rather than trial and error.
The emerging pattern for AI agent SDKs proves this matters. Consider the astroid/client middleware implementation for autonomous agents: configurable token bucket for request smoothing, respect for Retry-After on 429s, exponential backoff with jitter for transient failures. Without client-side rate limiting, agents overwhelm API gateways and halt operations. The pattern is spreading because it works.
Server-driven throttling, adding artificial latency as clients approach limits, is another pattern worth considering for internal APIs where consuming teams are known. It smooths the transition from fully allowed to fully blocked, giving client monitoring a chance to notice degraded response times before requests start failing outright.
The Verdict
Token bucket earns its popularity because it tolerates bursts real clients naturally produce, a mobile app catching up after network hiccups, a batch job starting its morning run, an AI agent making rapid sequential calls. Sliding window earns its place wherever precise, boundary-free counting matters more than burst tolerance.
The algorithm only does half the job. Clear signals back to clients, sensible per-endpoint limits, a defined failure mode for when the limiter itself struggles, and client-side backoff behavior transform rate limiting from a blunt instrument into infrastructure people barely notice.
That’s the point: how real-world systems handle traffic spikes beyond textbook rate limiting algorithms involves recognizing that burst tolerance without sustained rate control isn’t protection, it’s a highly sophisticated way to delay the inevitable outage.
The right question isn’t “which algorithm is better?” It’s “which failure mode can you tolerate?” Token bucket lets you choose exactly where your API breaks under pressure. That’s not a bug. That’s a feature.