MiniMax walked onto the stage on October 19th with a trailer that screams “Space Bunny”, a character that mysteriously topped global leaderboards while operating anonymously. As it turns out, Space Bunny processed more than 200 trillion tokens during its secret life, and was actually an early version of M3.1 Flash all along.
The reveal came with bold claims: nearly three times faster online inference, usage costs cut by 70%, and frontier-level performance on agentic tasks, coding, computer use, and cybersecurity. But here’s where it gets interesting, and a bit confusing.
Everyone heard “Flash” and assumed “small.” The community went digging for a compact model. What they found instead was a 428B total parameter MoE architecture with roughly 23B active parameters, sparse attention, and a native visual encoder.
Flash means fast, not small. And there’s a world of difference.
The Benchmark Story: Impressive Numbers, Real Caveats
Let’s talk about what M3.1 Flash actually does before we get into the “lightweight for edge” debate it’s sparked.
MiniMax’s official claims paint a picture of a model that punches way above its weight class on agentic benchmarks:
| Benchmark | Score | Context |
|---|---|---|
| DeepSWE v1.1 | 73.7% | Complex software engineering tasks |
| OSWorld V2 | 61.7 | AI computer operation, cross-app tasks |
| Agents’ Last Exam (ALE) | 29.6 | Real professional work evaluation |
| CyberGym | 82% | Vulnerability discovery & validation |
| BankerToolBench | 76.2 | Multi-step financial planning |
| AutomationBench-AA | Top tier | Enterprise SaaS workflows |
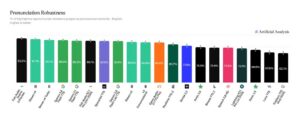
Independent verification from Artificial Analysis backs up the headline numbers: M3.1 Flash scores 43 on their Intelligence Index, placing it #4 overall and #21 when adjusted for context, well above the median of 13 for similarly priced models.
The model hits 48% on Humanity’s Last Exam, which puts it in the same conversation as models that cost ten times more per token. The long-context reasoning score of 79.7% on AA-LCR suggests the 1M token context window isn’t just for show.
Here’s the catch that nobody’s talking about enough: this model is verbose. When evaluated on the Intelligence Index, it generated 180M output tokens versus a median of 99M for comparable models. That’s nearly double the tokens to solve the same problems. At $0.60 per million output tokens, you’re paying for that verbosity, even if the price per token is remarkably low.
The Price-Performance Squeeze Nobody Asked For
At $0.15 per 1M input tokens and $0.60 per 1M output tokens, M3.1 Flash undercuts most of its competition while delivering comparable intelligence. The cache discount is particularly aggressive: cached input runs at $0.015 per 1M tokens, which is a 90% discount from the standard input rate.
The official pricing table paints a stark picture:
| Model | Input USD/1M tokens | Output USD/1M tokens | Cached input USD/1M tokens |
|---|---|---|---|
| MiniMax M3.1 Flash | $0.15 | $0.60 | $0.015 |
Yes, that’s a 90% cache discount. It makes M3.1 Flash extremely attractive for agentic workloads where you’re repeatedly feeding the same context, which is exactly how most agent frameworks actually operate.
At $0.22 per task on the Intelligence Index, M3.1 Flash is dramatically cheaper than the $5.98, $7.63 you’d pay for Claude models or the $3.26, $3.74 range for GPT-6 variants. Even the closest competitor, MiMo-V2.6-Pro at $0.13 per task, doesn’t offer the same breadth of capability.
The real kicker? The model manages 122.8 tokens per second output speed, beating the 115.8 tokens per second median. On their own infrastructure, MiniMax claims output speeds reach 200+ TPS with P50 speeds of 170+ TPS. That’s not marketing fluff, it’s confirmed by the Artificial Analysis speed data showing 123 tokens per second on standard tests.
“Flash” Doesn’t Mean What You Think It Means
Here’s where the community engagement gets spicy. The r/LocalLLaMA thread lit up with speculation about model size before the specs dropped. The top comment captured the uncertainty perfectly: “Do we know the size of M3? I don’t know how excited to be without knowing the size!”
The response was telling: “Probably 500B-1TB for M3.1 judging by HLE w/o tools.” That guess was remarkably close, the actual spec came in at 428B total parameters with about 23B active.
The term “Flash” has been diluted by vendors applying it to everything from 3B parameter phone models to 600B+ parameter cloud behemoths. When a community commenter noted that “Flash means fast not small”, they were identifying a genuine shift in how the industry talks about efficiency. Fast can mean small (sparse activation), or it can mean optimized infrastructure, or it can mean genuinely better architecture.
For M3.1 Flash, it’s a bit of all three. The “Flash” designation comes from more aggressive sparsity that reduces the compute needed per token, plus inference optimizations that make the model responsive. But 428B total parameters is not what most people would call “lightweight”, even if the 23B active parameter count is what you’d expect from a much smaller model.
The ownership question adds another wrinkle: this is listed as a proprietary model, even though MiniMax says weights are coming. The company has a history of releasing open weights, M2.1 and M2.5 shipped with permissive licenses, but this one carries more uncertainty.
Agentic AI: The Actual Use Case That Matters
Here’s the thing about M3.1 Flash that’s getting lost in the parameter count debates: it was built for agentic workloads, and the benchmarks reflect that focus.
The model’s performance on AutomationBench-AA puts it at the top of the chart at 78%, significantly ahead of GPT-6 Astra (68%), Grok 4.7 (67%), and Claude Opus 5.5 (71%). For enterprise automation, think sales workflows, marketing operations, customer service chains, finance tasks, HR processes, this model can complete real workflow across SaaS systems end-to-end.
On Terminal-Bench 4.0, which tests agentic coding and terminal use, M3.1 Flash hits 25.8%. That’s behind GPT-6 Astra’s 57% and Claude Sonnet 5.5’s 64%, but it’s competitive for the price point.
The cowork benchmark claim, 62% on Automation-Bench and 30% on ALE, tells the story MiniMax wants to tell: this is a model for AI agents that work alongside humans in real environments, not just a chatbot with extra steps.
The economics of agentic workloads are where the 90% cache discount really shines. Agent frameworks typically maintain large conversation contexts that get re-sent with each step. M3.1 Flash’s aggressive cache pricing makes long-running agents significantly more affordable than competitors.
Computer Use and Visual Reasoning: The Hidden Multimodal Capabilities
A detail buried in the official announcement is the model’s native visual encoder. M3.1 Flash accepts text and image inputs, with text output only. It ranks first among Chinese models on both OSWorld V2 (61.7 points) and ALE (29.6 points).
The BabyVision score of 91%, cited in the official X announcement, demonstrates strong visual reasoning capability. This makes sense with the OpenRouter integration listing support for text, images, and even video input with text output. For computer use tasks, where the model needs to interpret screenshots and UI states, this visual understanding is non-negotiable.
The multimodal capability is particularly interesting for the “frontend work” use case that MiniMax Code highlights. Understanding visual design, generating frontend code from mockups, and creating presentations all benefit from the visual encoder.
The Price of Speed: Security and Reliability Questions
No model release is complete without community skepticism, and M3.1 Flash has attracted its share. The licensing concern was immediately raised by developers who remember MiniMax’s history with M2.1, where a promised open-source release turned into a closed license.
The cybersecurity claims deserve scrutiny. An 82% score on CyberGym for vulnerability discovery is impressive, but it also raises questions about what happens when a model with frontier-level capabilities and aggressive pricing becomes widely available for penetration testing and malware analysis. The security community is simultaneously excited about the defensive applications and concerned about the offensive capabilities in the hands of less scrupulous actors.
There’s also the performance variability question. The OpenRouter availability data shows 99.82% availability over three days, which is solid, but tool call error rates of 5.14% indicate that agentic workflows aren’t as reliable as the benchmarks suggest.
What M3.1 Flash Means for the Model Landscape
The release of M3.1 Flash signals something important about where the industry is heading. As the trend continues, we’re seeing a split between two approaches:
- Massive frontier models (GPT-6, Claude Opus 5.5) that chase maximum intelligence at premium prices
- Efficient agentic models (M3.1 Flash, DeepSeek V4.1 Flash 1017, GLM-5.3 Flash) that optimize for real-world task completion at dramatically lower costs
The second category is where the economic disruption lives. When a model delivers 70-80% of frontier capability at 5-10% of the cost, enterprise adoption becomes a numbers game that the expensive models can’t win.
This aligns with the broader trend in model compression and efficiency we’re seeing across the industry. Tencent demonstrated that models can be compressed to 13% of their original size while retaining 98% of performance. MiniMax is applying different techniques, sparse activation and aggressive MoE routing, to achieve similar efficiency gains at inference time.
The 23B active parameters make M3.1 Flash theoretically deployable on consumer hardware. The community discussion includes speculation about running it on 24GB VRAM systems, with at least one developer prepping an Orange Pi 5 for the reference. If the weights release as promised on October 23rd and quantization is viable, we could see M3.1 Flash running on desktop hardware within weeks.
The Bottom Line
MiniMax M3.1 Flash represents a meaningful step forward in making frontier-adjacent AI affordable and deployable. At $0.15 per million input tokens with a 90% cache discount, it’s not just competitive, it’s in a different economic category than most comparable models.
But calling it “lightweight” requires context. 428B total parameters with 23B active is efficient, not small. It’s a model built for high-throughput API deployment, not necessarily for your phone or even your laptop. Flash means fast, and at 122-200 tokens per second, it delivers on that promise.
The real story here is the economics of agentic AI. When task completion costs drop to $0.22 per task on the Intelligence Index, versus $6-8 for frontier models, the calculus changes for building AI agents at scale. You can run ten times more experiments, iterate ten times faster, and deploy agents in contexts where cost previously made them infeasible.
The open weights promise and the eventual delivery of those weights on October 23rd will determine whether M3.1 Flash becomes a platform or just another impressive API. If MiniMax follows through with open weights and the community can get 23B active parameters running on consumer hardware, this could be the model that makes local agentic AI actually viable.
For now, M3.1 Flash is proof that the efficiency race is as important as the capability race. The model that wins the enterprise will be the one that solves real problems at costs that make sense, and MiniMax just made a very compelling case for being that model.